Can I Run Ornith-1.0-35B Locally? Q4 ~22 GB on 24 GB, Q8 Wants Dual 3090
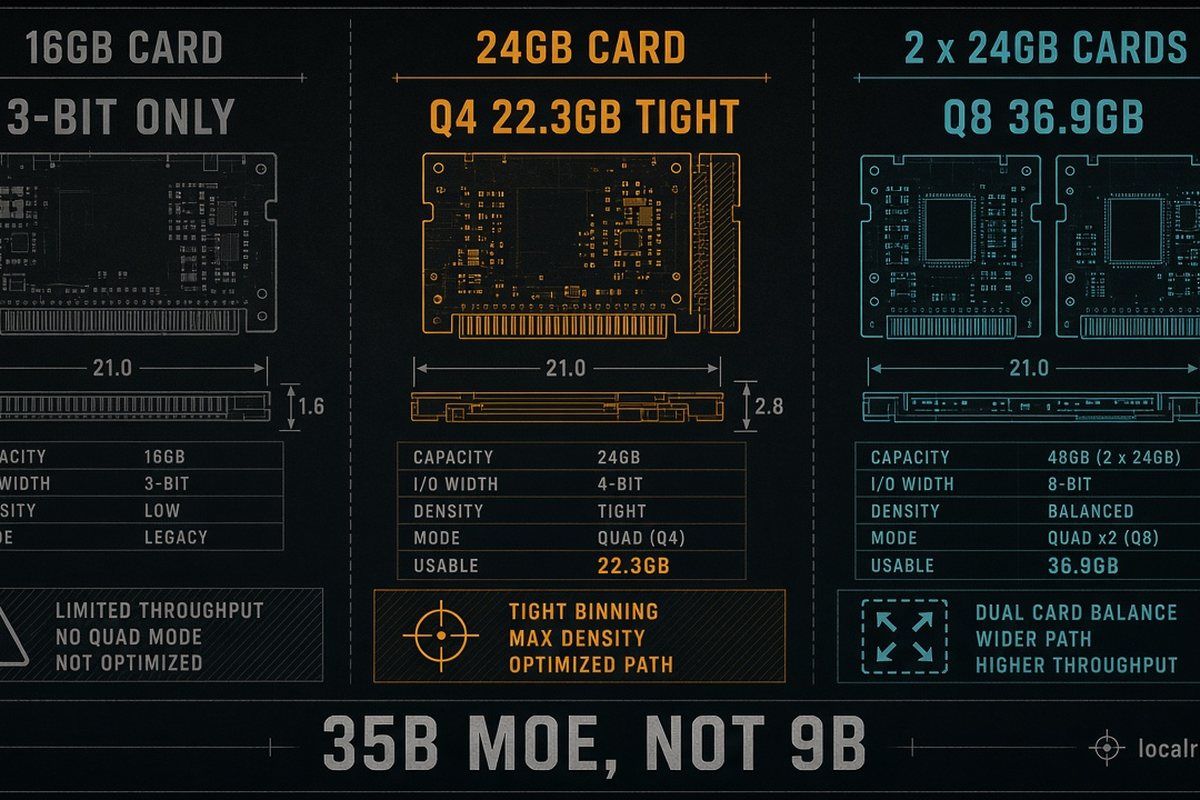
Short answer: Ornith-1.0-35B is the 35B-class MoE in the Ornith 1.0 family, not Ornith 9B. Unsloth UD-Q4_K_XL is 22.3 GB; Q8_0 is 36.9 GB (Hub ls, 2026-09-10). A used RTX 3090 is a tight Q4 cell. Dual 3090 is the Q8 conversation. A 16 GB card is 3-bit, not Q4. LocalRig has not measured tok/s.
What SKU is 35B?
Family card: 35B-MoE, not 9B-Dense. Unsloth GGUF base_model is deepreinforce-ai/Ornith-1.0-35B; tags include qwen3_5_moe. Official family copy lists 9B-Dense, 31B-Dense, 35B-MoE, 397B-MoE. This URL is 35B only. 397B is a skip/rent problem, not this page.
Hub overview for ornith-ai/Ornith-1.0-35B listed ~664.9K parameters on 2026-09-10. That cannot be reconciled with a 22.3 GB Q4 GGUF. Same class of metadata bug as 9B’s 1.5M overview. Trust file size.
GGUF file sizes (Hub ls, 2026-09-10)
| Quant | File size |
|---|---|
| UD-IQ1_S | 10.5 GB |
| UD-Q2_K_XL | 12.3 GB |
| UD-IQ3_XXS | 13.7 GB |
| UD-Q3_K_XL | 16.8 GB |
| MXFP4_MOE | 21.7 GB |
| UD-Q4_K_M | 22.1 GB |
| UD-Q4_K_XL | 22.3 GB |
| UD-Q5_K_XL | 26.5 GB |
| UD-Q6_K | 29.3 GB |
| Q8_0 | 36.9 GB |
File size is not KV. 22.3 GB on a 24 GB card leaves ~1–2 GB before CUDA and cache. Short sessions may load; a long agent window will not. LocalRig has no llama-fit-params packet. Cap context.
24 GB vs dual 3090 vs 16 GB
One 3090: Q4 tight. Dual 3090: Q8 / Q5. 16 GB: 3-bit. Q5_K_XL 26.5 GB already overflows one 24 GB card. Dual 3090 (48 GB) holds Q8_0 36.9 GB with KV room. That is the dual 3090 build use case — not because 9B needed two cards.
Browse used RTX 3090 24GB on eBay →
Check 16 GB cards on Amazon → only for UD-Q3 bands, not 22.3 GB Q4.
Rent a 48 GB or 24 GB box to compare: RunPod, Vast.ai, GPUMart. Two 3090s vs one 4090 if Q8 is the real constraint.
Runtime
Unsloth GGUF + llama.cpp is the documented class. No LocalRig tok/s. Ollama: no library+hardware packet on this page. Do not copy 9B -c 262144 onto 35B Q4 on 24 GB — the 9B file is 5.7 GB; this Q4 is 22.3 GB.
Related: Run llama.cpp on an RTX 3090. Ollama vs llama.cpp vs vLLM.
If you wanted “Ornith on 16 GB,” start at 9B. If you wanted 24 GB dense daily driver, Qwen 3.8 27B is still the LocalRig default; 35B Q4 is a tighter guest on the same card.
Q4 at 22.3 GB vs MXFP4_MOE at 21.7 GB is the same 24 GB-class problem: both load, neither leaves a 200k KV budget. Q5 at 26.5 GB is a dual-card or offload file. People who “just Q5 it for quality” on one 3090 will OOM. Dual 3090 PSU and case constraints are documented in the dual-3090 build guide — 350 W × 2 plus CPU is a 850 W-class PSU conversation, not a 450 W office SFF.
Compared with Gemma 4 31B (Unsloth 17–20 GB 4-bit dense) and GLM-4.7-Flash (~18 GB 4-bit MoE), Ornith 35B Q4 is the tightest 24 GB guest in this batch. If the used 3090 is for one daily driver, 27B Q4 or GLM-4.7-Flash 4-bit leave more KV than 22.3 GB Ornith Q4.
397B in the family list is not this page. Do not “Q2 it onto a 3090.” That SKU is closer to the Kimi skip class until a GGUF table is cited here.
Hub ~6.5M downloads on ornith-ai/Ornith-1.0-35B (2026-09-10) do not fix the ~665K parameter overview bug. File size wins.
A single 4090 (24 GB) is the same VRAM as a 3090 for this Q4 file. You are not buying Ada for 2 GB of extra room over 22.3 GB. Dual 3090 vs one 4090 is a bandwidth and 48 GB vs 24 GB question — two 3090s vs one 4090. Q8 36.9 GB needs 48 GB aggregate, so two 3090s beat one 4090 for Q8 weights. Q4 22.3 GB fits either 24 GB card; pick on used price.
Offload: llama.cpp can page 35B Q5 into host RAM. Unsloth’s usual warning applies — slower. LocalRig has no tok/s for 35B Q5 on 24 GB + 64 GB RAM. Leave it as a maybe, not a cell.
397B remains out of scope. If you wanted that family flagship, you wanted a skip/rent page, not a 22 GB Q4.
llama.cpp --fit on (when your build has it) can auto-offload experts. That is a procedure, not a 35B Q8-on-one-3090 promise. Measure peak VRAM or do not claim a cell. Hybrid attention on the family card is why 9B can talk about 262k; 35B Q4 on 24 GB still has almost no spare after 22.3 GB of weights. Start at 4k–16k context, not 262k.
PSU: PSU for a multi-GPU AI rig before you order a second 3090 for Q8.
Used-market 3090 vs 4090 is almost always a VRAM tie at 24 GB. Pay Ada tax only for bandwidth if you already measured a 35B bottleneck — LocalRig has not. eBay used 3090 + campid is the LocalRig default buy link for this Q4 cell. Amazon 4090 search is the new-card alternative; still 24 GB.
Quiet homelab: 350 W blower 3090s are loud. That does not change the 22.3 GB file.
If the used 3090 is already the daily driver for Qwen 3.8 27B, Ornith 35B Q4 is a guest, not a replacement that magically adds KV. 22.3 GB weights vs 27B Q4’s looser 24 GB fit is why this page calls the cell tight. Measure peak VRAM with the context you actually use, or keep 35B on dual-3090 / 48 GB.
Ollama: no LocalRig ornith:35b plus 3090 tok/s packet. llama.cpp + Unsloth GGUF is the documented class. Hybrid attention on the family card is why 9B can talk about 262k; do not copy that window onto 35B Q4 on 24 GB.
Who this is NOT for
- 9B shoppers. Different file, different VRAM.
- Q8-on-one-3090 buyers. 36.9 GB ≠ 24 GB.
- People trusting Hub’s ~665K parameter overview. The Q4 GGUF is 22.3 GB.
- Anyone needing LocalRig tok/s or filled long context on one 3090 Q4. Shortfalls stay visible.
- 397B shoppers. Not this URL.
Methodology
- Fit numbers: Hub ls of
unsloth/Ornith-1.0-35B-GGUF, 2026-09-10. File sizes, not traces. - SKU identity: Unsloth GGUF base_model
deepreinforce-ai/Ornith-1.0-35B; Hub overview parameter field treated as a discrepancy. - Speed: none first-party.
- LocalRig first-party: none as of 2026-09-10.
Sources
Frequently Asked Questions
Can I run Ornith-1.0-35B Q4 on a used RTX 3090?
Unsloth UD-Q4_K_XL is 22.3 GB on disk. A 24 GB 3090 can hold that file with little KV spare. Treat it as a tight Q4 cell, not a long-context promise. LocalRig has no first-party tok/s.
Does Q8 fit one 3090?
No. Q8_0 is 36.9 GB. Dual 3090 (48 GB) is the consumer split that can talk about Q8 weights plus modest KV.
Is this Ornith 9B?
No. 9B is dense ~5.7 GB Q4. 35B is the larger MoE. Hub overview listed ~665K parameters for ornith-ai/Ornith-1.0-35B — that conflicts with a 22 GB Q4 file. Trust the GGUF size.
16 GB card?
UD-IQ3_XXS is 13.7 GB; UD-Q3_K_XL is 16.8 GB. 16 GB is a low-bit conversation, not Unsloth Q4 22.3 GB plus KV.
How fast is it?
LocalRig has no first-party row. Do not invent dual-3090 tok/s.