Can I Run Ornith-1.5-122B Locally? Official Q4 Is 70.6 GiB
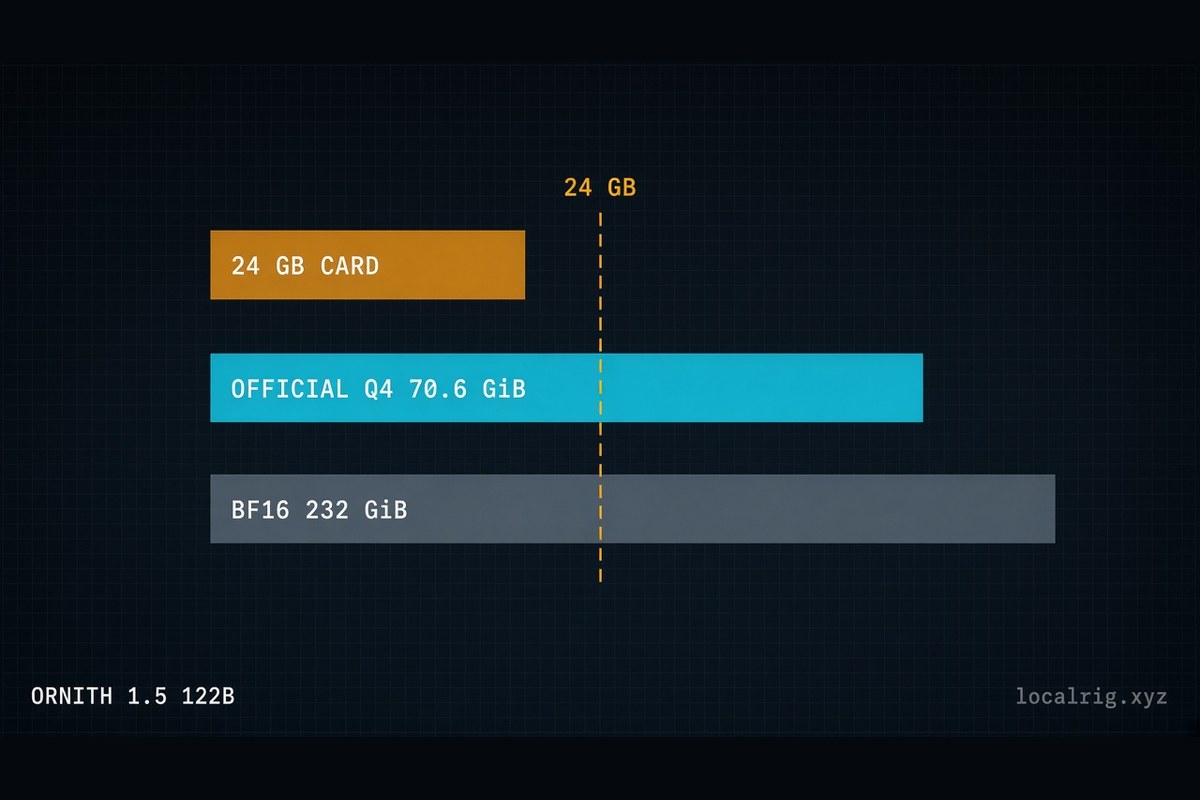
Short answer: Ornith-1.5-122B is an open-weight MoE with a 262,144-token window and an MIT tag on the model card. The official Q4_K_M GGUF is 70.6 GiB, so a 24 GB or 48 GB card cannot hold it. An 80 GB GPU is a Q4 file-size fit, not a fit for the 232 GiB BF16 file. LocalRig has no first-party tok/s.
This page is a constraint selector for the October 2026 122B checkpoint. It is not Ornith-1.0-9B and not Ornith-1.0-35B. Those pages use different files. Mixing the names is how a 24 GB card gets shopped for a 70 GiB download.
What SKU is Ornith-1.5-122B?
A 122B-class MoE in the Ornith 1.5 family, with a vision tower, a 262,144-token config window, and an MIT declaration on the card. The model card calls it a 122B MoE and says it is the largest member of that family writeup. Hugging Face safetensors metadata, read 2026-10-21, reports 125,086,497,008 BF16 parameters. At 2 bytes each, that is 250.17 GB, or 232.99 GiB, of weight bytes before file overhead. LocalRig does not average 122B and 125.09B into a third size. The name and the parameter count are both printed. They disagree.
config.json on that repo sets model_type to qwen3_5_moe, architecture Qwen3_5MoeForConditionalGeneration, 256 experts, 8 experts per token, hidden_size 3072, 48 layers, vocabulary 248,320, and max_position_embeddings 262,144. The layer list is 36 linear_attention layers and 12 full_attention layers. A vision_config is present, and the Hub tags include image-text-to-text. The card’s serving note asks for Transformers 5.8.1 or newer, vLLM 0.19.1 or newer, and SGLang 0.5.9 or newer. transformers_version in the config is 5.8.1.
The card’s YAML says license: mit, and the Hub tag list includes license:mit. The YAML links a LICENSE file. On 2026-10-21 a raw fetch of that path returned 404, and the repo sibling list had no LICENSE file. The Ollama library page for this tag also shows an MIT heading. The declaration is on the card. The license file itself was not in the tree LocalRig listed.
The announcement post from @ornith_ is timestamped 2026-10-20T14:36:13Z (9:36 AM Central). The Hub repo createdAt is 2026-10-16T07:14:27Z, and lastModified on the base repo was 2026-10-21T08:29:30Z. Those are three different timestamps. This page does not collapse them into one release instant. The same org listing, sorted by modification time the same day, also shows separate repos ornith-ai/Ornith-1.5-9B and ornith-ai/Ornith-1.5-35B-A3B with August 2026 modification times, plus GGUF, FP8, NVFP4, and MLX repos for the 122B. This URL is only the 122B.
generation_config.json sets temperature 0.6, top-k 20, top-p 0.95. The card also prints a second sampling list for general tasks at temperature 1.0, top-p 0.95, top-k 20, and presence penalty 1.5, and the 0.6 list for precise coding. Those are two vendor recipes. The assistant turn opens with a think block, per the card. Every think token is context.
Is the active size 9B or 10B?
The card does not say. The conflict stays open. config.json has expert counts and layer sizes. It has no active-parameter integer. StudioTVAI, read 2026-10-21, writes “125.1B parameters (9B active per token)” and says the figure is computed from the official config. The same page labels its calculator output as estimates. A TeksEdge post at 2026-10-20T16:30:00Z says the model is about 122B total and about 10B active, on a Qwen3.5-122B-A10B base. That active-count sentence is unverified against the Ornith card.
Qwen/Qwen3.5-122B-A10B config.json, fetched the same day, matches Ornith on model_type, 256 experts, top-8 routing, hidden size 3072, 48 layers, vocabulary 248,320, and context 262,144. The two files are not identical: Ornith records transformers_version 5.8.1 and a few fields the Qwen file omits. Matching shape is not a weight lineage, and the Qwen file also lacks an active-parameter integer. The “A10B” string is in the Qwen repo id. AtomicChat’s GGUF card states the same lineage and links that Qwen repo. Ornith’s own card says Ornith-1.0 was developed on Qwen3.5 and Gemma 4, and that 1.5 extends 1.0. It does not name Qwen3.5-122B-A10B.
LocalRig will not pick 9B or 10B. Speed depends on whichever active count is real. The download size depends on the total, which the safetensors header puts at 125.09B.
How large are the official files?
Byte sizes from the Hugging Face tree API on 2026-10-21. GiB is bytes / 1024³. Decimal GB is bytes / 10⁹. Vision projectors are separate files and are not inside the weight totals below.
| Repo | File | Bytes | Decimal GB | GiB |
|---|---|---|---|---|
ornith-ai/Ornith-1.5-122B-GGUF | Q4_K_M | 75,843,911,648 | 75.84 | 70.635 |
| same | Q5_K_M | 88,710,135,776 | 88.71 | 82.618 |
| same | Q6_K | 102,380,498,912 | 102.38 | 95.349 |
| same | Q8_0 | 132,555,710,048 | 132.56 | 123.452 |
| same | BF16 | 249,362,980,832 | 249.36 | 232.237 |
| same | mmproj BF16 | 912,263,200 | 0.91 | 0.850 |
ornith-ai/Ornith-1.5-122B-NVFP4 | safetensors sum | 77,627,904,940 | 77.628 | 72.297 |
ornith-ai/Ornith-1.5-122B-FP8 | safetensors sum | 132,949,613,832 | 132.950 | 123.819 |
ornith-ai/Ornith-1.5-122B-MLX-4bit | safetensors sum | 68,709,961,055 | 68.710 | 63.991 |
ornith-ai/Ornith-1.5-122B-MLX-8bit | safetensors sum | 129,745,735,601 | 129.746 | 120.835 |
The hero’s 70.6 GiB is 70.635 GiB rounded. The hero’s 232 GiB is 232.237 GiB rounded. StudioTVAI’s GGUF table, which says it reads ornith-ai/Ornith-1.5-122B-GGUF and leaves projectors out, prints Q4_K_M 70.6 GiB, Q5_K_M 82.6 GiB, Q6_K 95.3 GiB, Q8_0 123 GiB, and BF16 232 GiB. Those roundings match this tree. A second table on that page estimates 4-bit weights at 68.8 GiB and BF16 weights at 228 GiB. Those estimate cells do not match the files. This page uses the file bytes. It does not use StudioTVAI’s rental prices.
File size is not KV, and it is not a tok/s. The card’s llama.cpp snippet is llama-server -hf hf.co/ornith-ai/Ornith-1.5-122B-GGUF with -c 262144. That is a vendor command for the official GGUF repo. It is not a measurement that a 262,144-token window fits beside a 70.6 GiB file. The card also describes YaRN with factor 4.0 as a way to stretch the window toward 1,000,000 tokens in vLLM or SGLang, and it warns that the scaling applies to every request. That is a vendor switch. It is not a home-hardware fit.
How large is bartowski’s Q4, separately?
Bartowski’s Q4_K_M is a different file from the official Q4_K_M. The bartowski README prints Q4_K_M at 78.92 GB. The tree sum for Ornith-1.5-122B-Q4_K_M shards on 2026-10-21 is 78,921,736,736 bytes, which is 78.92 GB and 73.502 GiB. Official Q4 is 70.635 GiB. The two Q4 names are about 2.9 GiB apart. Do not merge the rows.
Other bartowski README sizes that the same tree sum matched, for the boundary cases on this page: IQ1_S 30.01 GB (27.948 GiB) and Q2_K 48.95 GB (45.585 GiB). The README calls IQ1_S extremely low quality and Q2_K very low quality. The repo was created 2026-10-20T17:04:56Z. Bartowski’s table is a publisher size list. It is not a LocalRig quality ranking and not a tok/s table.
unsloth/Ornith-1.5-122B-GGUF also exists on the Hub. This page does not quote it. Those shard bytes were not summed on 2026-10-21.
Which memory pool is larger than the file?
“Under” means the weight file is smaller than that GiB label. It does not mean the model loads, and it does not include KV, the runtime, or the operating system. NVIDIA’s “24 GB” on a 3090 is 24 GiB. A 128 GB figure on a box can mean 128 GiB or 128 decimal GB (119.21 GiB). Where that ambiguity changes the answer, the cell says so.
| File | GiB | 24 | 48 | 64 | 80 | 96 | 128 |
|---|---|---|---|---|---|---|---|
| Official Q4_K_M | 70.635 | over | over | over | under | under | under |
| Official Q5_K_M | 82.618 | over | over | over | over | under | under |
| Official Q6_K | 95.349 | over | over | over | over | under by 0.7 | under |
| Official Q8_0 | 123.452 | over | over | over | over | over | under by 4.5 if the pool is 128 GiB |
| Official FP8 | 123.819 | over | over | over | over | over | under by 4.2 if the pool is 128 GiB |
| Official BF16 GGUF | 232.237 | over | over | over | over | over | over |
| Official NVFP4 | 72.297 | over | over | over | under | under | under |
| Official MLX-4bit | 63.991 | over | over | under by 0.01 | under | under | under |
| bartowski Q4_K_M | 73.502 | over | over | over | under | under | under |
| bartowski IQ1_S | 27.948 | over | under | under | under | under | under |
AtomicChat AD-IQ3_XXS-IQ2_S | 44.371 | over | under | under | under | under | under |
A used RTX 3090 does not hold any official quant, any bartowski file in the README, or the AtomicChat file above. The smallest bartowski file LocalRig summed, IQ1_S, is still 27.948 GiB. Two 3090s are 48 GiB. Official Q4 is 70.635 GiB, so the pair is short by about 22 GiB before KV. Four 24 GiB cards are 96 GiB of aggregate VRAM, which is larger than the official Q4 file. LocalRig has no split-run packet for that wiring. Aggregate arithmetic is not a load.
Official Q6 at 95.349 GiB is under a 96 GiB label by less than 1 GiB. That is not a usable margin once the machine and the runtime take memory. Official Q8 at 123.452 GiB is under a 128 GiB pool by about 4.5 GiB and over a 128 decimal-GB pool (119.21 GiB). This page does not have a byte-count spec that says which of those a “128 GB” Spark or Mac actually is. Q8 on that label stays unresolved. Official MLX-4bit at 63.991 GiB is under 64 GiB by about 0.01 GiB. Treat 64 GiB as too small for that official MLX file.
The 24 GB card that still makes sense in this cluster is the one already documented for Qwen 3.8 27B, Ornith 9B, and a tight Ornith 35B Q4. Those are different downloads.
If the goal is to try the official Q4 file on a single 80 GB-class GPU before buying hardware, rent that class of GPU. RunPod, Vast.ai, and GPUMart list datacenter and consumer shapes. This page has no dated rental price. A used 3090 is the wrong card for this file. The buy link for that card lives on the used RTX 3090 guide and on the 9B and 35B pages.
Browse used RTX 3090 24GB on eBay → only if the job is the 9B or 35B page. It is not the 122B Q4 job.
What does the “single 80 GB GPU” sentence refer to?
The card states it. The BF16 checkpoint does not fit that sentence. The GGUF README says the model “serves on a single 80GB GPU” and then prints a vLLM command for ornith-ai/Ornith-1.5-122B, the base repo, with --max-model-len 262144. The base safetensors count is 125,086,497,008 BF16 parameters. The official BF16 GGUF is 232.237 GiB. An 80 GiB GPU cannot hold that file.
Files from the official org that are smaller than 80 GiB, before KV: Q4_K_M at 70.635 GiB, and NVFP4 safetensors at 72.297 GiB. Files that are larger: Q5_K_M at 82.618 GiB, Q6, Q8, FP8, MLX-8bit, and BF16. Bartowski Q4_K_M at 73.502 GiB is also under 80 GiB, with less spare than the official Q4 file. None of those comparisons are a measured nvidia-smi trace. The announcement post says the model runs “on a single NVIDIA DGX card.” That is a vendor sentence. It is not a VRAM trace and not a tok/s.
What do Ollama, llama.cpp, and vLLM actually publish?
Tags and commands. Not a hardware packet from LocalRig. The Ollama tags page, read 2026-10-21, lists ornith-1.5:122b (digest ea3e29aebeb8) as 73–77 GB, 256K context, text and image input, updated 23 hours earlier. Named tags beside it: ornith-1.5:122b-q4_K_M at 77 GB (f1e64af05b7d) and ornith-1.5:122b-nvfp4 at 73 GB (f0df8c3e9efc). The library text says “Release Ornith-1.5-122B (Oct 20, 2026).” The same page lists ornith-1.5:9b at 6.6 GB and ornith-1.5:35b at 23 GB, both about two months old. Those tags are not this 122B file and they are not the Unsloth 1.0 sizes on the other LocalRig pages. The run command the library prints is ollama run ornith-1.5:122b. There is no tok/s next to it.
llama.cpp on the Ornith card points at the official GGUF repo and context 262144. vLLM on the card points at the base repo. Both are procedures. Related runtime context, without borrowed speed numbers: Ollama vs llama.cpp vs vLLM.
What single-source speed numbers exist?
Two community cards, both labeled as such. LocalRig has not rerun either.
0xBakeer / TandemLLM publishes an EXL3 pack at 4.0 bits per weight, “64.7 GB in all,” converted from the BF16 repo at revision e09bc0dfbe with exllamav3 1.6.2. The speed section says one DGX Spark (GB10, 128 GB), nothing else running, TandemLLM at commit 88b8070e (the 0.13.0 line), one request, 512 greedy tokens, thinking off, a fresh server per row. Plain decode on that table: prose 37.6 tok/s, code 38.4, chat 37.8, edit 38.0, copy 38.1, game file 37.2. With the MTP layer plus lookup: prose 85.3, code 114.2, chat 110.0, edit 115.9, copy 124.8, game file 103.3. The card says each drafted run matched the plain greedy text token for token. It also says the weights took 59.95 GiB in memory and 61.16 GiB with the MTP layer, with about 47 GB still reported available after the load, and prefill of 1,217 to 1,442 tok/s at 3,664 and 4,597 tokens. The tool-eval section on the same card is dated 2026-10-21. The speed table itself has no separate run date. This is one publisher, writing about their own engine. It is not a GGUF result and not a LocalRig row. Spark context for the machine, not for this model: DGX Spark 64GB vs 128GB and DGX Spark vs dual RTX 3090.
oMLX benchmark 9tjdv8ya is titled ornith-1.5-122b-mlx-DFlash2. The hardware block says M3 Ultra (60-core), 96 GB, 60 GPU cores. Software: oMLX v0.7.1, macOS 27.0. Settings on the page include dflash_enabled: true, mtp_enabled: false, and TurboQuant KV at affine8 / 8-bit. The page does not print a GGUF quant name. Generate tok/s and peak memory on the context table: 1k → 54.2 tok/s, 67.0 GB; 4k → 53.5, 70.0 GB; 16k → 49.6, 70.1 GB; 32k → 18.4, 75.2 GB; 64k → 41.2, 75.6 GB. The 32k row is slower than the 64k row on the same table. This page does not smooth that. A resource panel on the same URL lists a peak footprint of 76.88 GB, separate from the per-context peaks. No run date was visible on the page when it was read 2026-10-21. One source, one stack, DFlash on. Do not quote 54.2 tok/s as a plain MLX or GGUF figure.
What about the day-0 EXL3 build and the 47.6 GB Mac claim?
The EXL3 repo is real. The tweet’s Mac run is not a cite packet.
@MiaAI_lab, 2026-10-20T15:03:21Z, calls an EXL3-EAQ v1 build a day-0 download “for one DGX Spark or RTX PRO 6000.” The Hub repo Mia-AiLab/Ornith-1.5-122B-EXL3-EAQv1-4-bpw was created 2026-10-20T06:45:52Z, which is earlier the same UTC day than the Ornith announcement post. The README states 65,542,591,754 bytes of weights (65.5 GB, 61.041 GiB), exllamav3 v1.6.1, and a 63.4 GiB peak after load with a small cache. The sanity section does not name the GPU. The “Not tested” section says throughput was not measured. The tweet names Spark and RTX PRO 6000. The load number does not. LocalRig has not loaded the shards. There is no tok/s to cite from this card.
The TeksEdge post says a 47.6 GB AtomicChat GGUF is for 64 GB Macs, that people already have it running in llama.cpp, and that the active size is about 10B. The running-on-Macs sentence and the 10B sentence do not include a runtime version, a quant filename, a context length, and a tok/s together. Those two claims stay unverified.
The file size does not stay unverified. On AtomicChat/Ornith-1.5-122B-GGUF, the single file Ornith-1.5-122B-AD-IQ3_XXS-IQ2_S.gguf is 47,643,074,624 bytes (47.643 GB, 44.371 GiB). The README prints that file at 47.6 GB, KL divergence 0.13030, top-1 agreement 86.05%, measured by AtomicChat against BF16 on 4× H100 80GB. That KL run is a quality check on datacenter GPUs. It is not a 64 GB Mac tok/s. Their Q8_0 shard sum is 132,555,710,592 bytes (132.556 GB), matching the README’s 132.6 GB. AD-IQ4_XS-IQ3_S sums to 62,151,958,784 bytes (62.152 GB, 57.884 GiB), matching the README’s 62.2 GB row.
The same README then disagrees with itself about 64 GB. The fit table maps 64 GiB to AD-IQ4_XS-IQ3_S. A later note says a 64 GB Mac should take AD-IQ3_XXS-IQ2_S, the 47.6 GB file. The TeksEdge post follows the note. LocalRig does not pick a winner, and it has no llama-fit-params dump for either file. Both files are under a 64 GiB label. Neither file has a LocalRig speed row. AtomicChat also states a 24 KB-per-token cache and context headroom in that fit table. That column is theirs.
What do the vendor quality scores say?
Vendor-reported. Not a LocalRig ranking, and not a VRAM table. The announcement post prints SWE-bench Verified 0.845 and BrowseComp 0.785. The model-card table prints the same scores as 84.5 and 78.5. The card’s SWE footnote says SWE-bench Verified, Pro, and Multilingual used the OpenHands harness, temperature 1.0, top-p 0.95, a 256K context window, and an anti-hack rule. The card’s Ornith column also prints SWE-bench Pro (no-hack) at 76.9, against 43.9 for the Qwen3.8-Flash-Next column on the same row. BrowseComp on that row is 78.5 versus 75.3 for Flash-Next. The card footnote list does not give BrowseComp its own harness line. Do not attach the SWE footnote to BrowseComp.
Two post figures do not match the card table, so this page does not average them. The post prints TB2.1 as 0.813. The card prints TerminalBench 2.1 as 81.2. The post prints a single HLE of 0.446. The card prints HLE with tools at 48 and HLE without tools at 37.68. Use the card cells for those rows.
Who this is NOT for
- 24 GB and 48 GB shoppers. Official Q4 is 70.635 GiB. A 3090 and a dual-3090 box are the 9B and 35B conversations.
- Anyone treating “single 80 GB GPU” as the BF16 checkpoint. The BF16 GGUF is 232.237 GiB. Q4 and NVFP4 are the official files under 80 GiB.
- Anyone who needs one active-parameter count. The card does not publish 9B or 10B. Both figures exist only as third-party statements.
- Anyone quoting 54 tok/s or 38 tok/s as a GGUF 3090 number. Those rows are one EXL3 Spark card and one DFlash oMLX page. LocalRig has no first-party tok/s.
- Anyone who wants a filled 262,144-token window because the config says 262,144. The config is a maximum. KV for this hybrid stack is unmeasured here.
- Shoppers using the August 2026 Ornith-1.5-9B or 35B-A3B repos, or the older Ollama 9b and 35b tags, as if they were this file.
Methodology
- Weights: Hugging Face tree byte sizes for the official GGUF, FP8, NVFP4, and MLX repos, plus bartowski and the named AtomicChat files, read 2026-10-21. GiB is bytes/1024³. Decimal GB is bytes/10⁹. No dense “2 GB per billion” estimate is used as a file size.
- Identity: Ornith card,
config.json, safetensors total, andgeneration_config.json. The 9B versus 10B active count is left unresolved because neither the Ornith card nor the compared Qwen config prints the integer. - Speed: none first-party. 0xBakeer and oMLX are single-source community cards. Mia’s 63.4 GiB peak names no GPU. AtomicChat’s KL table is a 4× H100 quality check.
- Dates:
dataDateis 2026-10-21, the day these pages and trees were read. It is not a LocalRig measurement date. This template isconstraint_selector. The page states no price, sopriceDateis unset. A later price would belong ondataDatewhile this stays a guide. It would belong onpriceDateonly if the template were changed tobenchmark, so a price refresh would not move a measurement date. - LocalRig first-party: none as of 2026-10-21.
Sources
- ornith-ai/Ornith-1.5-122B — card, config, generation config, safetensors count (2026-10-21).
- ornith-ai/Ornith-1.5-122B-GGUF — official GGUF byte sizes.
- Official org listing — GGUF, FP8, NVFP4, and MLX repos.
- bartowski/Ornith-1.5-122B-GGUF — separate Q4_K_M at 78.92 GB.
- StudioTVAI file-size table — rounds that match the official GGUF tree; 9B active is their estimate.
- @ornith_ announcement — 2026-10-20T14:36:13Z; vendor scores.
- Ollama ornith-1.5:122b — tag sizes, read 2026-10-21.
- 0xBakeer EXL3 4.0 — single-source Spark tok/s.
- oMLX 9tjdv8ya — single-source M3 Ultra, DFlash on.
- Mia-AiLab EXL3-EAQ v1 and the day-0 post.
- AtomicChat GGUF — 47.643 GB file verified; Mac tok/s not included.
- TeksEdge post — unverified for the Mac run and the 10B active count.
- Can I run Ornith-1.0-9B locally? and Can I run Ornith-1.0-35B locally?.
- Qwen/Qwen3.5-122B-A10B config — shape comparison only.
Frequently Asked Questions
Can I run Ornith-1.5-122B on a used RTX 3090?
No. The official Q4_K_M GGUF is 70.635 GiB (75,843,911,648 bytes), read from the Hugging Face tree on 2026-10-21. A 24 GB card is 24 GiB. Bartowski's smallest listed file, IQ1_S, is 27.948 GiB, still over 24 GiB. Two 3090s are 48 GiB, still under the official Q4 file. LocalRig has no tok/s for this model.
How much VRAM does Ornith 1.5 122B Q4 need?
The official ornith-ai Q4_K_M file is 70.635 GiB, which rounds to the 70.6 GiB figure on the hero. That is the weight file, not KV cache. Bartowski's Q4_K_M is a different file at 78.92 GB (73.502 GiB). An 80 GiB GPU can hold the official Q4 file with spare before KV. It cannot hold the official Q5 file at 82.618 GiB.
Is Ornith-1.5-122B the same as Ornith 9B or Ornith 35B?
No. Ornith-1.0-9B Q4 is a 5.7 GB dense file. Ornith-1.0-35B Q4 is about 22.3 GB. This page is the October 2026 122B-class MoE. Ollama also lists older ornith-1.5:9b and ornith-1.5:35b tags. Do not reuse those sizes here.
Is the active size 9B or 10B?
Unresolved. The Ornith model card and config.json do not print an active-parameter count. Safetensors reports 125,086,497,008 BF16 parameters. StudioTVAI estimates 9B active. A TeksEdge post says about 10B and names Qwen3.5-122B-A10B. That Qwen config matches the expert and layer counts and still has no active-parameter integer.
Does the model fit on one 80 GB GPU?
The model card says it serves on a single 80GB GPU, in the paragraph above a vLLM command for the base repo. The base checkpoint is 125.09 billion BF16 parameters, about 232.99 GiB of weight bytes, and the official BF16 GGUF is 232.237 GiB. Official Q4_K_M at 70.635 GiB is the file that is smaller than 80 GiB. Official Q5_K_M at 82.618 GiB is not.
How fast is it on a DGX Spark or an M3 Ultra?
LocalRig has not measured it. One publisher card, 0xBakeer, reports plain EXL3 4.0 decode at 37.6 to 38.4 tok/s on one DGX Spark, and higher with that card's MTP drafter. One oMLX page reports 54.2 tok/s at 1k context and 18.4 at 32k on an M3 Ultra with 96 GB, with DFlash enabled. Both are single-source. Neither is a LocalRig row.