Nemotron 3.5 Bolt: what the 74B '24GB' and the E4B '4GB' really need
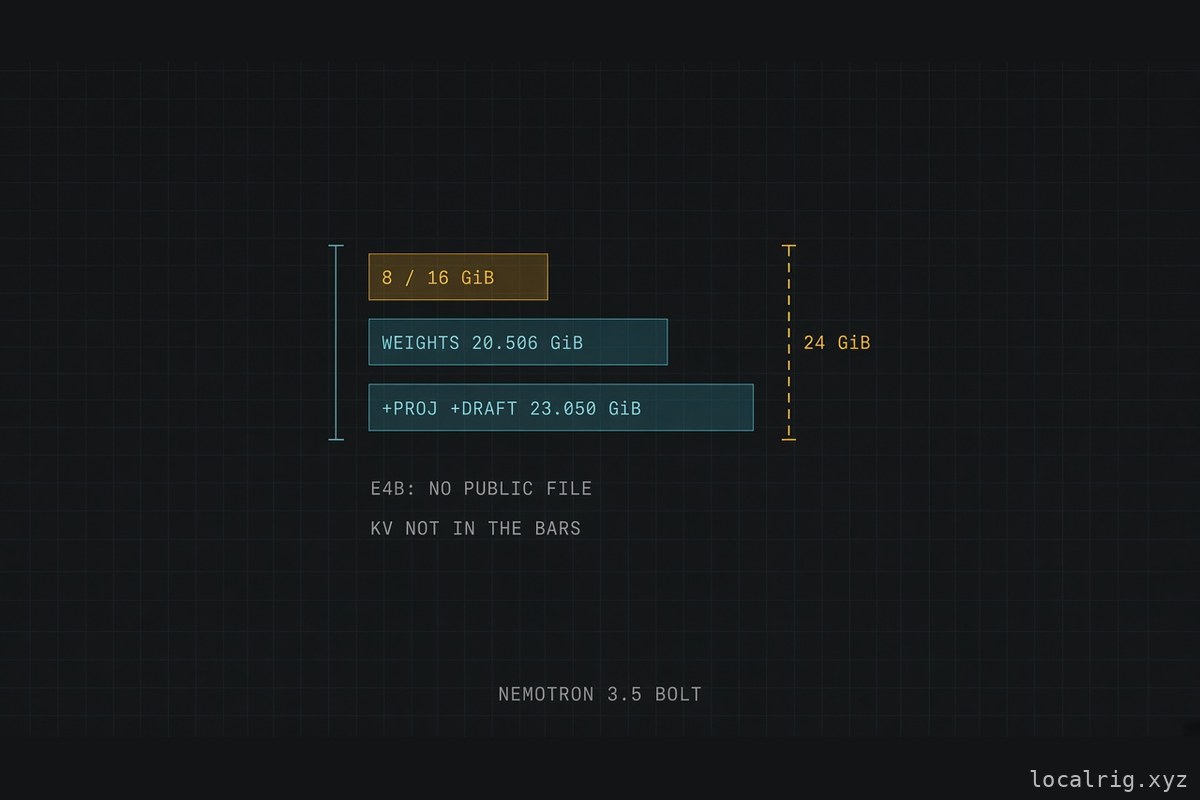
Short answer: The official Nemotron 3.5 Bolt 74B-A9B GGUF is 22.018 GB (20.506 GiB). With the 1.734 GB projector and 0.998 GB drafter it is 23.050 GiB, under a 24 GiB card before KV cache. NVIDIA’s llama.cpp recipes start at 32 GB. Bolt E4B’s 4 GB claim is announced for 23 October 2026, with no public weights yet.
This page checks those two memory names against file bytes, the context flags on the model card, and the runtimes that actually load the checkpoint. It is a constraint selector for the October 2026 Bolt pair. A 74B total size is a different download from the dense 70B hardware guide.
Specs, as published on 22 October 2026
The 74B row is a model card plus files. The E4B row is an announcement.
| Bolt 74B-A9B | Bolt E4B | |
|---|---|---|
| Name on the NVIDIA blog | Nemotron 3.5 Bolt 74B-A9B 24GB | Nemotron 3.5 Bolt E4B 4GB |
| Total / active parameters | 74B / 9B, on the model card | No parameter count on the blog or a model card |
| Architecture | Mamba-2–Transformer hybrid LatentMoE, C-RADIO v4-H vision encoder | Not stated |
| Experts per token | 9, in config.json (num_experts_per_tok) and on the card (top-K fixed at 9, down from 22 in the parent) | Not stated |
| Precision of the shipping checkpoint | IQ2, quantization-aware. Experts IQ2_XXS at 2.0625 bits. Mamba projections NVFP4. Embeddings and the output layer Q8_0 | Not stated |
| Context integer | max_position_embeddings 262144. The card also writes “up to 256K” | Not stated |
| License | OpenMDW-1.1 on the 74B cards | The blog calls the trio open models and does not link an E4B license file |
| Weight file read here | GGUF 22,018,326,528 bytes | No repository under nvidia on Hugging Face, 22 October 2026 |
| Card release date | Hugging Face 10/15/2026 | Blog: coming Oct. 23 |
The GGUF repo createdAt is 2026-10-07T19:15:58Z and lastModified is 2026-10-15T18:10:28Z. The card’s release line is 10/15/2026. Those are two timestamps. This page keeps both.
How big are the 74B files?
Bytes from the Hugging Face tree API on 22 October 2026. Decimal GB is bytes / 10⁹. GiB is bytes / 1024³, shown to three decimals.
| File | Bytes | Decimal GB | GiB |
|---|---|---|---|
Official GGUF NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB.gguf | 22,018,326,528 | 22.018 | 20.506 |
| Official mmproj | 1,733,692,736 | 1.734 | 1.615 |
| Official LiLiCorr GGUF drafter | 998,242,560 | 0.998 | 0.930 |
| Those three files added | 24,750,261,824 | 24.750 | 23.050 |
| Official 24GB-repo safetensors, 90 files | 24,083,745,496 | 24.084 | 22.430 |
| Official LiLiCorr safetensors, 1 file | 962,485,872 | 0.962 | 0.896 |
| Safetensors plus that drafter | 25,046,231,368 | 25.046 | 23.326 |
| Official BF16 safetensors, 63 files | 149,774,331,136 | 149.774 | 139.488 |
Unsloth IQ2_XXS | 22,018,326,464 | 22.018 | 20.506 |
Unsloth UD-IQ1_S | 18,507,811,840 | 18.508 | 17.237 |
Unsloth UD-IQ2_M | 24,607,493,120 | 24.607 | 22.918 |
Unsloth UD-Q2_K_XL | 28,753,128,448 | 28.753 | 26.778 |
Unsloth UD-Q3_K_XL | 39,027,158,016 | 39.027 | 36.347 |
Unsloth UD-Q4_K_XL | 50,219,478,368 | 50.219 | 46.771 |
| Duckets MLX 4-bit safetensors | 43,148,056,718 | 43.148 | 40.185 |
| nativ-community MLX 5-bit safetensors | 52,419,593,497 | 52.420 | 48.820 |
Unsloth’s IQ2_XXS is 64 bytes smaller than the official GGUF. Both round to 22.018 GB and 20.506 GiB. They are separate files. Unsloth’s mmproj-BF16.gguf is 1,733,692,672 bytes, also 64 bytes under the official projector. The Unsloth DFlash NVFP4 drafter is 998,242,560 bytes, the same byte count as NVIDIA’s LiLiCorr GGUF.
The technical report says compression takes a 148 GB BF16 model to a 22.1 GB quantized model. The BF16 tree sum on 22 October is 149.774 GB. The official GGUF is 22.018 GB. The report’s round numbers and the tree bytes sit next to each other. This page does not average them.
A GeForce card sold as 24 GB has 24 GiB, which is 25.770 decimal GB. A strict 24.000 decimal GB label is a smaller bucket. The three-file GGUF sum is 24.750 decimal GB and 23.050 GiB, so it is over a 24.000 decimal GB label and under a 24 GiB card.
Which 8, 16, 24, 32, and 48 GiB pools clear the file?
“Under” means the weight bytes are smaller than that GiB label. It leaves out KV cache, the vision runtime, CUDA or Metal overhead, and the operating system. The same GiB label is the comparison for a discrete GPU and for a Mac configuration sold with that much unified memory. The loader is a separate question, below.
“Under by” is (pool × 1024³ − file bytes) / 1024³, rounded to three decimals. It is the byte remainder, not a second measurement.
| File | GiB | 8 | 16 | 24 | 32 | 48 |
|---|---|---|---|---|---|---|
| Official GGUF weights | 20.506 | over | over | under by 3.494 | under | under |
| Weights + mmproj | 22.121 | over | over | under by 1.879 | under | under |
| Weights + mmproj + drafter | 23.050 | over | over | under by 0.950 | under by 8.950 | under |
| vLLM safetensors sum | 22.430 | over | over | under by 1.570 | under | under |
| vLLM safetensors + LiLiCorr safetensors | 23.326 | over | over | under by 0.674 | under | under |
| Unsloth UD-IQ1_S | 17.237 | over | over by 1.237 | under | under | under |
| Unsloth UD-Q2_K_XL | 26.778 | over | over | over by 2.778 | under by 5.222 | under |
| Unsloth UD-Q4_K_XL | 46.771 | over | over | over | over | under by 1.229 |
| Duckets MLX 4-bit | 40.185 | over | over | over | over | under by 7.815 |
| nativ MLX 5-bit | 48.820 | over | over | over | over | over by 0.820 |
| Official BF16 safetensors | 139.488 | over | over | over | over | over |
An 8 GiB pool is short of every language-model file in the table. A 16 GiB pool is short of Unsloth’s smallest listed file here, UD-IQ1_S at 17.237 GiB. There is no 74B quant on this page that is a 16 GiB file-size fit.
A 24 GiB pool holds the official three-file set with 0.950 GiB left, and the safetensors-plus-drafter set with 0.674 GiB left. That remainder is the entire budget for KV, activations, and the framework. NVIDIA’s own llama.cpp deployment table does not use a 24 GB row. It lists:
| Hardware line on the GGUF card | Recipe name | Context flag | Drafter tokens | KV flags in the recipe |
|---|---|---|---|---|
| RTX Spark 128 GB, or a discrete GPU of 48 GB+ | 32 GB recipe | 262,144 | 7 | none printed |
| RTX Spark 64 GB, or a discrete GPU of 32 GB+ | 28 GB recipe | 65,536 | 6 | --cache-type-k q8_0 and --cache-type-v q8_0 |
The opening quick-start block on the same card is a third flag set: --ctx-size 98304, six draft tokens, and q8_0 KV. The card does not assign that block a VRAM number. Three context integers appear on one page: 98,304, 65,536, and 262,144. The summary line still says “up to 256K”.
The GGUF card’s supported-microarchitecture line names NVIDIA Ada Lovelace and NVIDIA Blackwell, on Windows and Linux. Ampere is absent from that line. A used RTX 3090 is a 24 GB Ampere card. An RTX 4090 is a 24 GB Ada card, which matches the architecture line and misses the 32 GB+ recipe line. An RTX 5090 is 32 GB and Blackwell, which matches the 28 GB / 65,536-token recipe’s hardware line. It is under the 48 GB+ line attached to the 262,144-token recipe. Is the RTX 5090 worth it for local AI? is the 32 GB card page. The used RTX 3090 buying guide is the 24 GB Ampere page, for a card the Bolt GGUF compatibility line does not name.
Spark boxes are in the recipe table at 64 GB and 128 GB, beside the 32 GB+ and 48 GB+ discrete rows. Memory split for those machines is on DGX Spark 64GB vs 128GB and RTX Spark laptops: which config.
What the report’s 24 GB estimate includes
Table 2 of the 15 October 2026 technical report is an estimate for batch size 1, context 131,072, and a Mamba prefill chunk of 8,192. Section 8.2 says the weights occupy 22.01 GB, cache and activations add 0.87 GB, and the subtotal is 22.87 GB before the drafter. The drafter line is 0.96 GB. The text-only total is 23.83 GB, with 0.17 GB left inside a 24 GB target. The vision encoder and projector are a separate BF16 line of 1.68 GB, and the report says that line is excluded from the text-only target.
The KV piece inside the 0.87 GB is one row: FP8 KV cache, 0.54 GB, at that 131,072-token setting. The table also lists a BF16 Mamba SSM cache of 0.08 GB and a Q8_0 activation buffer of 0.25 GB. Adding the report’s 23.83 GB text total to its own 1.68 GB vision line is 25.51 GB. That sum is arithmetic on two printed rows. It is not a profiled footprint. 25.51 decimal GB is over a 24.000 decimal GB label and under a 24 GiB card, because 24 GiB is 25.770 decimal GB. The llama.cpp recipes above use q8_0 KV at 65,536 tokens, or an unnamed KV type at 262,144 tokens. Those are different caches from the 0.54 GB FP8 row. This page does not scale 0.54 GB up to 262,144 tokens.
The official GGUF at 22.018 GB matches the report’s 22.01 GB weight subtotal to the hundredth of a decimal GB. The mmproj file at 1.734 GB and the report’s 1.68 GB vision line are close and unequal. The safetensors sum at 24.084 GB matches neither 22.01 nor 22.01 + 1.68. The tree sum and the table stay separate.
Which runtime loads which file?
llama.cpp v0.7.0 has the architecture. The 15 October tag is the build that crashes on Metal. Ollama’s library page says Metal is unsupported. MLX on a Mac is a community conversion with its own file size. ExLlamaV3 v1.6.4 added a loader on 20 October.
llama.cpp pull 30520 merged at 2026-10-15T13:34:57Z and adds NemotronH_Omni_Reasoning_V3 for Super 3.5 VL and Bolt 74B-A9B, including the vision projector and image and video paths. The git tag v0.7.0 points at commit 620d2225, tagged 2026-10-15T17:13:13Z. The Metal bug report names that commit as build 11669. The version-bump pull, merged the same afternoon, lists Nemotron Bolt 74B-A9B under new models via that pull. LiLiCorr draft support is the same release’s pull 30506. The GGUF card tells the reader to build llama.cpp from source and then pass --spec-type draft-dflash.
Issue 30610, opened 15 October 2026, reports a Metal segfault in ggml_metal_op_mul_mat_id on the first request. The report’s build line is 0.7.0-dev (build 11669, commit 620d2225c), the v0.7.0 commit. Hardware in the report: Apple M1 Max, 32 GB. Model: an Unsloth IQ2_XXS GGUF, text only. The diagnosis in the thread is that Bolt routes 9 experts per token and the Metal mul_mm_id map0 kernel had no <9> instantiation. Pull 30699 merged on 20 October 2026 and adds that instantiation. The v0.7.0 tag predates the merge. A binary built from the 15 October tag is the crashing build. A binary built from master after 20 October contains the merged fix. This page did not rebuild either one.
On 16 October 2026, itsandyking commented on that issue that the <9> fix, built at f12aaa3, then decoded at about 6 tok/s on an M3 Ultra with 96 GB. The comment attributes that rate to the official GGUF storing Mamba ssm_in / ssm_out projections as NVFP4, which Metal does not run, so those matmuls fall back to CPU. The comment’s workaround rewrites only those tensors to Q8_0 and says the file grows from 22.0 GB to 24.2 GB. That is one comment. Single-source. The tilde and the rounded gigabytes are the comment’s. LocalRig did not rerun it.
The Ollama library page, read 22 October 2026, lists three tags, latest, 74b-a9b, and 74b-a9b-iq2. Each line shows 25 GB, a 256K context, and text plus image input. All three display digest d6d3deeca271, so the library is offering one blob under three names. The page says NVIDIA provides CUDA deployment instructions and that Apple Silicon / Metal is not currently supported. It also says usable context depends on memory, and that images, history, tool results, and output share the budget. The page’s “updated” line was the relative text “1 week ago” on the day this article was written, which is not a calendar timestamp, so this page does not convert it into a date. The 25 GB label is larger than the 22.018 GB GGUF and near the 24.750 GB three-file sum. This page did not download the blob, so it does not claim which of those files are inside the 25 GB.
Duckets’ MLX 4-bit card, repo created 2026-10-15, says the conversion is from the BF16 checkpoint, 4-bit group size 64, and “40.2 GiB”. The safetensors sum is 40.185 GiB. The card says text and image were checked in mlx-vlm, and that a 128 GB Apple Silicon Mac loaded it. It also says LM Studio at upload time could miss the nemotron_h_omni package, and that KV-cache quantization had to be off for that app’s vision path. Those are the publisher’s notes. The 40.185 GiB file is over a 32 GiB Mac and under a 48 GiB Mac by 7.815 GiB before KV.
nativ-community’s 5-bit card, created 2026-10-16, pins the BF16 source revision bca0a8cb and says the weight files are 52.42 GB decimal, which matches the tree sum of 52.420 GB (48.820 GiB). That file is over a 48 GiB pool by 0.820 GiB before KV. The card reports a 64-token greedy code sample at 63.6 tok/s on an Apple M5 Max with 128 GB, MLX 0.32.4, with peak MLX memory of 59.58 GB across short checks. Single-source, the publisher’s smoke test. The card says the source context limit was not benchmarked. Best Mac for local LLM inference is the machine guide. The 5-bit file’s pool is the 128 GB class, in the company of other large MLX ports, not the 48 GB row.
ExLlamaV3 v1.6.4, published 2026-10-20T23:53:45Z, lists “Support Nemotron 3.5 Bolt (extend NemotronHForCausalLM)”. The README architecture table, read 22 October 2026, names NemotronH_Omni_Reasoning_V3 and marks image and video input. No EXL3 byte size was in the NVIDIA trees summed above. Support in the release notes is a loader. It is not a VRAM trace.
The vLLM card’s summary deployment line says a 24 GB packed model on NVIDIA Ampere (A100), Hopper (H100-80GB), or Blackwell. The software-integration line on the same card says Blackwell SM120 and SM121, and Linux. Those two lines were both on the card on 22 October 2026. This page keeps the disagreement. The quick start pins container vllm/vllm-openai:nightly-77154ca6116ae34cbfe314beef1016bde9b63989, --max-model-len 262144, --kv-cache-dtype fp8, bfloat16 Mamba cache, and a DFlash drafter with 7 speculative tokens. The NVIDIA blog of 15 October lists llama.cpp, Ollama, LM Studio, Unsloth, and vLLM as supported. This page did not launch an LM Studio build, so LM Studio stays a blog line.
Runtime choice for a GGUF you already have is the general comparison at Ollama vs llama.cpp vs vLLM. Bolt’s flags are the ones in the GGUF card, including --temp 1.0 and --top-p 0.95.
Is there an independent tok/s figure?
The cite packets that name a URL, a date, the model, the quant, the runtime, and the hardware are a 128 GB Windows laptop, a 128 GB Mac, and a 96 GB Mac. None of them is a 24 GB discrete GPU.
NVIDIA’s Table 8, in the 15 October report, measures llama.cpp on Windows 11 ARM on one Surface Laptop Ultra with 128 GB. With LiLiCorr, AIPerf SPEED-Bench-Coding is 83.99 TPS and AA-AgentPerf Local replay duration is 600.80 seconds. The same table prints Qwen3.6 35B-A3B UD-Q4_K_M at 96.63 TPS, Gemma 4 26B-A4B UD-Q4_K_M at 100.56 TPS, and Qwen3.8 27B UD-Q4_K_M at 28.26 TPS, on that same machine. Vendor measurements. LocalRig has not reproduced them. They describe a 128 GB unified-memory laptop, which is the recipe table’s larger Spark row, not the 0.950 GiB remainder on a 24 GiB card.
The two other numbers are the single-source notes above: 63.6 tok/s on the nativ 5-bit MLX card, 128 GB M5 Max, 64 generated tokens; and about 6 tok/s in the 16 October llama.cpp comment, M3 Ultra 96 GB, after the Metal expert fix and before any NVFP4 rewrite. Both stay labeled as the author’s figure.
NVIDIA’s accuracy table is a separate object from speed. On the GGUF card the IQ2 column is GDPVal-AA-V2 28.47, Terminal-Bench 2.1 50.98, BrowseComp 66.75, PinchBench 87.82, GPQA Diamond 86.43. The blog calls this checkpoint the top open model in its class on PinchBench and second on BrowseComp. Those are NVIDIA’s scores. The comparison rows include Gemma 4 26B-A4B, whose Unsloth 4-bit band on that other page is 16–18 GB, and Qwen 3.8 27B, which remains the dense 24 GB daily-driver page here. Borrowing Bolt’s benchmark column as a tok/s for either of those models would mix two pages.
What is actually known about E4B?
The 4 GB name is the announcement. There is no weight file to put in the fit table.
The NVIDIA blog, published 2026-10-15T15:00:24Z and still showing article:modified_time 2026-10-21T02:06:41Z when read on 22 October, says Nemotron 3.5 Bolt E4B 4GB is optimized for intelligence per GB for fast conversational agents, and that it is coming Oct. 23. A later paragraph says it is built for physical and conversational agents on GeForce RTX, Jetson, and RTX/DGX Spark, and that it combines conversation with multi-turn agent work for local voice assistants, interactive characters, and embedded interfaces. The post groups E4B with Super VL and the 74B as open models. It prints no parameter count, no active-parameter count, no context length, no quant, and no weight URL for E4B.
A Hugging Face API search on 22 October 2026 for Nemotron-3.5-Bolt-E4B limited to author nvidia returned no model. Until a tree listing exists, an 8 GiB or 16 GiB pool has nothing from E4B to be under or over. The 74B section above is the wrong file for a machine someone bought because a 4 GB name sounded like a laptop model.
Operator fill-in: when the E4B weights are public, replace this section with the tree byte size, the context integer from config.json, the license file, and the runtime recipe. Leave the 4 GB sentence in place as the 15 October announcement, dated, next to the file bytes.
Where a 32 GB or 48 GB pool comes from
The published discrete recipe for 65,536 tokens asks for 32 GB or more. The published recipe for 262,144 tokens asks for 48 GB or more. A 24 GiB card clears the three-file byte check and is outside both recipe rows.
Check RTX 5090 32GB on Amazon when the purchase is the 32 GB+ line on the GGUF card. Browse used RTX 3090 24GB on eBay when the machine is already a 24 GB Ampere card and the question is the card you have, which the GGUF compatibility line does not list. Rent a 32 GB or 48 GB GPU and load the official GGUF before treating the 0.950 GiB remainder as a working context: RunPod, Vast.ai, GPUMart.
A 16 GB card that already runs a small local model is a different purchase. gpt-oss-20b is the 16 GB page. Bolt 74B’s smallest file in the table above is 17.237 GiB.
Who this is NOT for
- Anyone treating the 24GB in the model name as a finished 24 GB load. The three-file GGUF is 23.050 GiB before KV. The published llama.cpp rows start at 32 GB+.
- Anyone buying for E4B on 22 October 2026. The blog dates the weights to Oct. 23. No NVIDIA repository was listed.
- Anyone downloading the BF16 repo for a 48 GB machine. The safetensors sum is 139.488 GiB.
- Anyone quoting 83.99 TPS for a 24 GB GeForce card. That figure is NVIDIA’s, on a 128 GB Surface Laptop Ultra.
- Anyone expecting the 15 October llama.cpp tag to answer on a Mac. Issue 30610 is that tag, on Metal, and it crashes. The kernel fix merged five days later.
- Anyone using a dense 70B calculator on the 9B-active count. Active experts change the matmul. They do not shrink the 22.018 GB file. Every expert is in the download.
Methodology
- File sizes: Hugging Face tree API, 22 October 2026. GiB = bytes / 1024³, decimal GB = bytes / 10⁹, both displayed to three decimals. “Under by” uses the unrounded byte difference against the GiB label.
- 24 GB estimate: NVIDIA technical report Table 2 and section 8.2, document date 15 October 2026. Vendor estimate at batch 1 and 131,072 tokens. Vision is the report’s excluded line.
- Recipes: GGUF model card, read 22 October 2026. Context flags 98304, 65536, and 262144 are quoted as printed.
- Runtimes: llama.cpp v0.7.0 tag
620d2225(15 October 2026), issue 30610, pull 30699 (merged 20 October 2026), Ollama library page, ExLlamaV3 v1.6.4 release notes, vLLM model card. No binary was built for this page. - Speed: NVIDIA Table 8 is vendor, on a 128 GB Surface Laptop Ultra. The 63.6 tok/s figure is the nativ-community card’s smoke test. The ~6 tok/s figure is one GitHub comment on 16 October 2026. Single-source where stated. No first-party run. No 24 GB discrete-GPU tok/s met the cite bar used here.
- E4B: NVIDIA blog HTML read 22 October 2026, plus an empty
nvidia-author search for the E4B repo name.dataDateis the day those pages and trees were read. It is not a LocalRig measurement date. This page states no price, sopriceDateis unset. - LocalRig first-party: none as of 22 October 2026.
Sources
- NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB model card,
config.json, and safetensors byte sum (accessed 2026-10-22). - NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-GGUF card and tree bytes (accessed 2026-10-22).
- LiLiCorr GGUF and BF16 tree sums (accessed 2026-10-22).
- Technical report, 15 October 2026.
- NVIDIA blog, 15 October 2026, HTML read 2026-10-22 (
modified_time2026-10-21). - llama.cpp pull 30520, v0.7.0, issue 30610, pull 30699.
- ExLlamaV3 v1.6.4.
- Ollama nemotron-3.5-bolt, read 2026-10-22.
- Unsloth GGUF tree, Duckets MLX 4-bit, nativ-community MLX 5-bit.
- Can I run Qwen 3.8 locally?, Can I run Gemma 4 26B-A4B locally?, Hardware to run a 70B model locally.
Frequently Asked Questions
Does Nemotron 3.5 Bolt 74B fit in 24 GB?
The official GGUF is 22,018,326,528 bytes, 22.018 GB, 20.506 GiB. Adding the 1.734 GB projector and the 0.998 GB LiLiCorr drafter makes 24,750,261,824 bytes, 23.050 GiB. That is under a 24 GiB card by 0.950 GiB before KV cache, activations, and the runtime. NVIDIA's llama.cpp card lists discrete-GPU recipes at 32 GB+ and 48 GB+, and its compatibility line names Ada Lovelace and Blackwell.
What does the 24GB in the model name measure?
NVIDIA's technical report, 15 October 2026, estimates a text-only deployment at 23.83 GB for batch 1 and 131,072 tokens, including a 0.96 GB drafter, and lists the vision encoder and projector as a separate 1.68 GB line excluded from that 24 GB target. The estimate is not a profiled load on a 24 GB GeForce card.
Can I run the 256K window on 24 GB?
config.json sets max_position_embeddings to 262144. The GGUF card's 262,144-token llama.cpp recipe is the 32 GB recipe for RTX Spark 128 GB or a discrete GPU of 48 GB+. The 32 GB+ recipe uses 65,536 tokens. The report's KV line is 0.54 GB of FP8 cache at 131,072 tokens, which is a third context length.
Does llama.cpp, Ollama, MLX, or ExLlamaV3 run it?
llama.cpp v0.7.0, tagged 15 October 2026 at commit 620d2225, includes pull 30520. That same commit segfaults on Metal; pull 30699, merged 20 October 2026, adds the 9-expert kernel. Ollama's library page lists a 25 GB tag and says Apple Silicon / Metal is not currently supported. Community MLX ports exist. ExLlamaV3 v1.6.4, published 20 October 2026, adds Bolt support.
Is Nemotron 3.5 Bolt E4B out, and does 4 GB match a file?
The NVIDIA blog, read 22 October 2026, still says Bolt E4B is coming Oct. 23. A Hugging Face search of the nvidia organization for Nemotron-3.5-Bolt-E4B returned no repository that day. Parameter count, context length, quant, and license for E4B were not on a model card. The 4 GB figure is the announcement.
How fast is Bolt on a 24 GB card?
LocalRig has no first-party tok/s. NVIDIA's report measures 83.99 TPS on a 128 GB Surface Laptop Ultra with llama.cpp and LiLiCorr, which is a vendor figure on a different machine. No independent cite packet on this page is a 24 GB discrete-GPU run.