Can I Run LFM2.5-24B-A2B Locally? Official Q4 Is 13.529 GiB
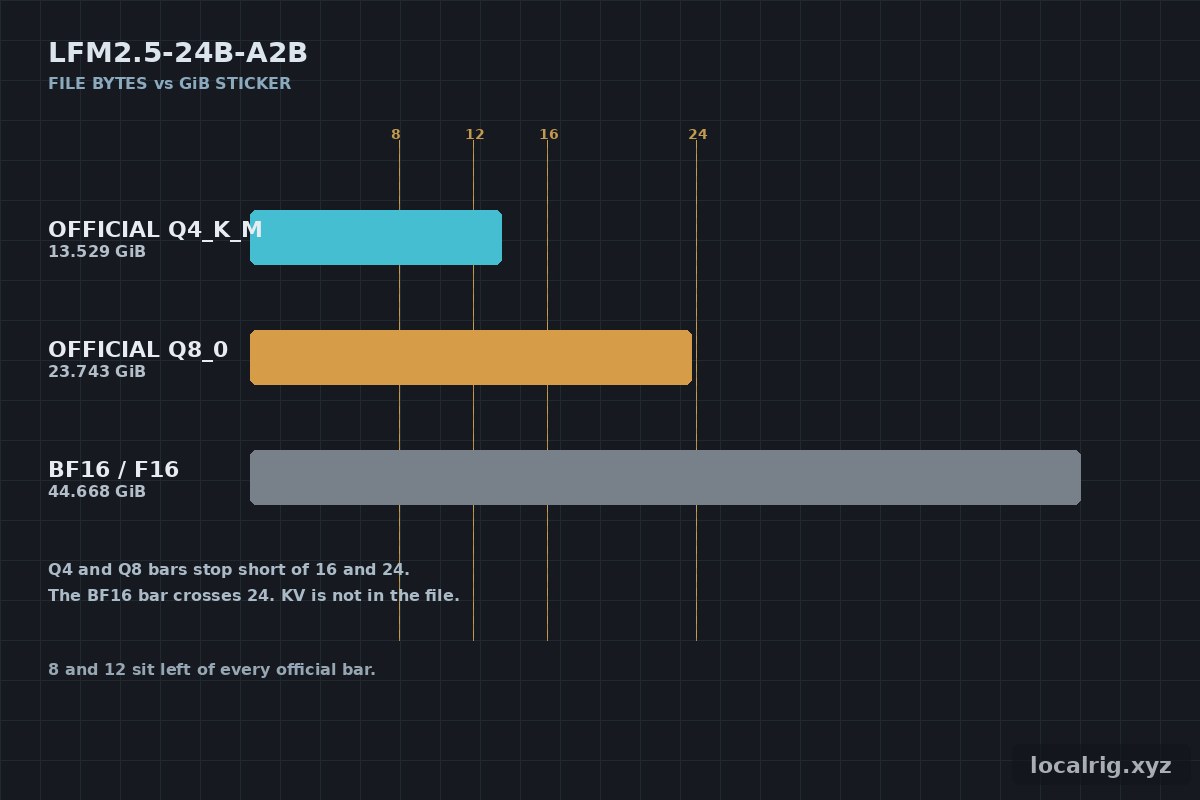
Direct answer: Liquid AI’s LFM2.5-24B-A2B is a text-only mixture-of-experts model. The card lists 24.0B total parameters, 2.45B active, and 131,072 tokens of context. The official Q4_K_M GGUF is 13.529 GiB: under a 16 GiB sticker and over 12 GiB. NVIDIA’s 21 October 2026 post names day-zero support and states no VRAM figure. LocalRig has not measured tokens per second.
There is no other LocalRig page for an LFM or Liquid model. This page is only LFM2.5-24B-A2B. The card says it keeps the LFM2-24B-A2B architecture and changes two things: context grows from 32K to 131K, and the vocabulary grows from 65K to 128K. It also says this checkpoint always thinks before it answers. Do not reuse an older LFM2 file size here.
What does the model card actually specify?
The detailed feature list on LiquidAI/LFM2.5-24B-A2B, read 22 October 2026, is the spec this page uses.
| Field | What the card says |
|---|---|
| Total parameters | 24.0B |
| Active parameters | 2.45B in the feature list. The same card’s summary table says “24B (2B active)“ |
| Layers | 40: 30 double-gated short convolution blocks + 10 GQA |
| Experts | 64 per MoE block, top-4 routing |
| Context length | 131,072 tokens |
| Vocabulary | 128,000 |
| Modality | Text only. The card calls it a general-purpose text reasoning model |
| Training budget | 36 trillion tokens |
| Sampling | temperature 0.1, top_k 50, repetition_penalty 1.05 |
| License name on the card | lfm1.0, file title LFM Open License v1.0 |
config.json on that repo, read the same day, agrees on the counts and does not repeat every name. architectures is Lfm2MoeForCausalLM. model_type is lfm2_moe. num_hidden_layers is 40. layer_types is a list of 40 entries: 30 conv and 10 full_attention. num_experts is 64. num_experts_per_tok is 4. num_dense_layers is 2. vocab_size is 128000. max_position_embeddings is 131072. hidden_size is 2048. num_attention_heads is 32 and num_key_value_heads is 8. The phrase “double-gated” is the card’s wording. It is not a key in that config file.
The Hub safetensors block on the same repo does not say 24.0B. It reports 23,971,585,280 BF16 parameters, 2,432 F32 parameters, and a total of 23,971,585,280. That total matches the BF16 count and does not add the F32 count. Adding the two dtype counts gives 23,971,587,712. The GGUF repo’s Hub gguf.total field is also 23,971,587,712, and its context_length is 131072. This page does not average 24.0B and 23.97B.
Active parameters are a second disagreement, and it is only a wording disagreement on the sources read here. The card’s feature list says 2.45B. The card’s opening line and its model table say 2B. Liquid’s docs say “2B active” and “only 2B active parameters per token.” NVIDIA’s 21 October post says “just 2 billion.” Ollama’s library text says “about 2B.” None of those pages show the arithmetic behind 2.45B. This page does not derive an active count from config.json.
The card says the model is not the one to use alone for knowledge-heavy tasks, and that retrieval or web search is the pairing it wants. That is a vendor scope note, not a memory figure. Quality scores on the card, including LiveClaw 48.09 against Qwen3.6-35B-A3B at 38.19, are vendor evals. LocalRig has not rerun them. The Qwen model in that sentence is 35B-A3B. LocalRig’s Qwen 3.6-27B page is a different SKU.
Hub createdAt for LiquidAI/LFM2.5-24B-A2B is 2026-10-12T05:35:46Z. The official GGUF repo’s createdAt is 2026-10-09T18:03:23Z, and its lastModified is 2026-10-13T21:33:53Z. This page does not pick one timestamp as a press-release date.
How big are the official files?
Decimal GB below is bytes / 10^9. GiB is bytes / 2^30. A “16 GB” GPU sticker is treated as 16 GiB, because that is 16 × 2^30 bytes of addressable memory. The same rule is used for 8, 12, and 24. File size is not a measured load. KV cache, runtime overhead, and the operating system are outside the file.
Official GGUF files on LiquidAI/LFM2.5-24B-A2B-GGUF, Hub tree API, 22 October 2026. The repo’s GGUF metadata names the architecture lfm2moe.
| File | Bytes | Decimal GB | GiB |
|---|---|---|---|
| LFM2.5-24B-A2B-QAD-Q4_0.gguf | 13,578,190,880 | 13.578 | 12.646 |
| LFM2.5-24B-A2B-Q4_K_M.gguf | 14,526,258,464 | 14.526 | 13.529 |
| LFM2.5-24B-A2B-Q5_K_M.gguf | 17,029,602,592 | 17.030 | 15.860 |
| LFM2.5-24B-A2B-Q6_K.gguf | 19,689,405,728 | 19.689 | 18.337 |
| LFM2.5-24B-A2B-Q8_0.gguf | 25,493,732,640 | 25.494 | 23.743 |
| LFM2.5-24B-A2B-BF16.gguf | 47,962,094,880 | 47.962 | 44.668 |
| LFM2.5-24B-A2B-F16.gguf | 47,962,094,880 | 47.962 | 44.668 |
BF16 and F16 are the same byte count on that tree. This page does not claim the bytes are the same weights. The GGUF card says the Q4_0 file in the repo is the quantization-aware distillation checkpoint, LFM2.5-24B-A2B-QAD-Q4_0.gguf, trained to recover accuracy lost to Q4_0. That is Liquid’s description of the file. It is not a LocalRig quality test, and it does not make the file smaller than 12 GiB.
Official MLX safetensors shard sums, tokenizer excluded. tokenizer.json on these repos is 17,905,598 bytes. Adding it does not move any sticker result below.
| Repo | Shard bytes | Decimal GB | GiB |
|---|---|---|---|
| LFM2.5-24B-A2B-MLX-4bit | 13,567,294,335 | 13.567 | 12.636 |
| LFM2.5-24B-A2B-MLX-5bit | 16,530,307,802 | 16.530 | 15.395 |
| LFM2.5-24B-A2B-MLX-6bit | 19,493,321,709 | 19.493 | 18.155 |
| LFM2.5-24B-A2B-MLX-8bit | 25,484,884,997 | 25.485 | 23.735 |
| LFM2.5-24B-A2B-MLX-bf16 | 47,953,192,738 | 47.953 | 44.660 |
Liquid’s docs, read 22 October 2026, say MLX needs mlx-lm>=0.32.0 and that earlier versions route the experts incorrectly. The docs also point at the 5-bit, 6-bit, and 8-bit repos. The model card’s format table names the 4-bit MLX repo and does not list the others in that table.
Which community quants are smaller than the official Q4?
Two public GGUF trees were sized the same day. They are community quantizations of this model, not Liquid’s official files, and not LocalRig measurements.
unsloth/LFM2.5-24B-A2B-GGUF, Hub createdAt 2026-10-13, lastModified 2026-10-20:
| File | Bytes | GiB |
|---|---|---|
| UD-IQ2_XXS | 7,468,302,592 | 6.955 |
| UD-IQ2_M | 7,535,313,152 | 7.018 |
| UD-Q2_K_XL | 8,042,561,760 | 7.490 |
| UD-IQ3_XXS | 8,959,328,480 | 8.344 |
| UD-Q3_K_XL | 10,947,100,928 | 10.195 |
| UD-Q4_K_XL | 14,876,901,632 | 13.855 |
| UD-Q5_K_XL | 17,918,820,608 | 16.688 |
| UD-Q6_K_XL | 21,861,204,224 | 20.360 |
| Q8_0 | 25,493,733,344 | 23.743 |
| BF16 | 47,962,095,584 | 44.668 |
bartowski/LiquidAI_LFM2.5-24B-A2B-GGUF, Hub createdAt 2026-10-14. The repo card says the quants used llama.cpp release b11606 and an imatrix. That build tag is bartowski’s statement. This page did not rebuild the files.
| File | Bytes | GiB |
|---|---|---|
| IQ2_XS | 7,485,563,296 | 6.971 |
| IQ2_S | 7,956,504,992 | 7.410 |
| IQ2_M | 8,783,561,120 | 8.180 |
| Q2_K | 9,178,317,216 | 8.548 |
| IQ3_XXS | 10,326,540,704 | 9.617 |
| IQ3_XS | 10,881,106,336 | 10.134 |
| Q3_K_S | 10,977,034,656 | 10.223 |
| Q3_K_M | 11,552,211,360 | 10.759 |
| Q3_K_L | 12,244,607,392 | 11.404 |
| IQ3_M | 12,591,980,960 | 11.727 |
| IQ4_XS | 13,378,191,776 | 12.459 |
| Q4_0 | 13,647,430,048 | 12.710 |
| Q4_K_S | 14,271,349,152 | 13.291 |
| Q4_1 | 15,072,969,120 | 14.038 |
| IQ4_NL | 15,177,318,816 | 14.135 |
| Q4_K_M | 15,351,906,720 | 14.298 |
| Q4_K_L | 16,369,549,728 | 15.245 |
| Q5_K_S | 17,189,011,872 | 16.009 |
| Q5_K_M | 18,499,207,584 | 17.229 |
| Q6_K_S | 20,179,026,336 | 18.793 |
| Q6_K | 21,154,202,016 | 19.701 |
| Q6_K_L | 22,226,895,264 | 20.700 |
| Q8_0 | 25,493,733,792 | 23.743 |
| bf16 | 47,962,095,712 | 44.668 |
Bartowski’s Q4_K_M is 14.298 GiB. Liquid’s official Q4_K_M is 13.529 GiB. Same quant name, different file. Unsloth’s UD-Q4_K_XL is 13.855 GiB, also not the official Q4. The three Q8_0 files land on 23.743 GiB at three decimals and differ by hundreds of bytes: official 25,493,732,640, Unsloth 25,493,733,344, bartowski 25,493,733,792.
mlx-community also hosts preview conversions of lq-preview/LFM2.5-24B-A2B-Preview at revision f772950ce6f17d35af5469d00334b61a9c2fc034, not the release checkpoint. Shard sums on 22 October 2026: Preview-4bit 13,487,150,319 bytes (12.561 GiB) and Preview-mxfp4 12,738,173,592 bytes (11.863 GiB). The preview cards round those to about 13.49 GB and 12.74 GB. The mxfp4 preview is under 12 GiB. The official MLX 4-bit sum is not. Do not use the preview to answer the release-weight question.
Which stickers are the files under?
“Under” means the file has fewer bytes than N × 2^30. “Over” means it does not fit in that sticker even before KV cache. A Mac at the same sticker gets the same file result. Unified memory also holds the operating system. This page does not subtract a macOS reserve, because it has no measurement of one.
| Sticker | Official GGUF under it | Official GGUF over it | What a smaller community file changes |
|---|---|---|---|
| 8 GiB | None | QAD-Q4_0 is 12.646 GiB | Unsloth UD-IQ2_XXS 6.955, UD-IQ2_M 7.018, UD-Q2_K_XL 7.490. Bartowski IQ2_XS 6.971 and IQ2_S 7.410. Bartowski IQ2_M is 8.180 and is over |
| 12 GiB | None | QAD-Q4_0 is 0.646 GiB over | Largest bartowski file still under: IQ3_M at 11.727 GiB. Next, IQ4_XS, is 12.459 and over. Unsloth UD-Q3_K_XL is 10.195 and under. UD-Q4_K_XL is 13.855 and over |
| 16 GiB | QAD-Q4_0, Q4_K_M (2.471 GiB of file spare), Q5_K_M (0.140 GiB of file spare). MLX 4-bit and 5-bit too | Q6_K is 18.337 GiB. MLX 6-bit is 18.155 GiB | Bartowski Q5_K_S is 16.009 GiB, just over 16. Unsloth UD-Q5_K_XL is 16.688 GiB and over. Official Q5_K_M stays under |
| 24 GiB | Q6_K and Q8_0. Q8_0 leaves 0.257 GiB before KV. MLX 6-bit and 8-bit too | BF16 and F16 are 44.668 GiB. MLX bf16 is 44.660 GiB | The community Q8 files are also under 24 GiB. They do not create a new 24 GiB answer |
A 32 GiB sticker and a 36 GiB sticker still miss the 44.668 GiB BF16 and F16 files. The BF16 file is 8.668 GiB over 36 GiB. A 48 GiB sticker is the first one in this table that those files are under: 3.332 GiB of file spare before KV. A 64 GiB sticker is under by more. Those two Mac sizes are sticker arithmetic on the same bytes. They are not an MLX load test.
Active parameter count does not shrink the file. All of the experts sit in the GGUF. A 2.45B active figure is a speed story on Liquid’s card, not a license to treat this as a 2B dense download. The quantization explainer is the general memory math. It is not a substitute for the byte counts above. The buying framework is the same split: capacity is whether the file fits, bandwidth is how fast a fit decodes, and this page has the first and not the second.
If you are buying a 16 GB card because the official Q4 and Q5 files are under that sticker, the new-card search is a 16 GB GeForce, with the 0.140 GiB Q5 spare called out so a long context is not assumed.
Check RTX 4060 Ti 16GB on Amazon →
A 24 GB card is the first sticker here that the official Q8 file is under, with 0.257 GiB of file spare. That is a weights-file fact. It is a poor reason to expect a 131,072-token context on the same card. People shopping that sticker on the used market are in the used RTX 3090 guide. LocalRig’s dense default on that card is still Qwen 3.8 27B, which is a different file.
Browse used RTX 3090 24GB on eBay →
An 8 GB or 12 GB card does not get an official Q4. The RTX 3060 12GB guide is about smaller dense models. Pointing it at this official Q4 file is the wrong file. A community Q3 can be under 12 GiB. That is a lower-bit file, and this page has no quality comparison against Q4_K_M.
Gemma 4 26B-A4B is the other small-active MoE the Liquid card names. Unsloth’s band there is 16–18 GB at 4-bit, which is a vendor band, not this GGUF. GLM-4.7-Flash is a 30B-A3B with a different Unsloth file. gpt-oss-20b is the other 16 GB-class download LocalRig already sizes, and its file is not this one.
Renting a 24 GB GPU is a way to see whether Q8 actually loads before buying the card. File spare of 0.257 GiB is the reason to try it rather than assume it. RunPod, Vast.ai, and GPUMart are the rental paths. A 16 GB rental answers the official Q4 file. It does not answer Q8.
What did NVIDIA announce on 21 October 2026?
NVIDIA’s blog post “Bringing the Spark to Europe,” by Gerardo Delgado, is dated 21 October 2026. Two sentences in it mention this model, and they do not say the same thing as the bullet list at the top.
The opening bullets include “Day-0 support for new Nemotron, GLM, DeepSeek, Qwen, MiniMax and FLUX.3 AI models.” Liquid and LFM are not in that bullet.
The section “New Models With Day-Zero Support” says NVIDIA is adding day-zero model support for Nemotron Bolt E4B 4B, GLM, DeepSeek, Qwen, MiniMax, Liquid AI’s LFM2.5-24B-A2B, and FLUX.3 Klein. A later sentence says Liquid AI’s LFM2.5-24B-A2B is an open-weights reasoning model that activates just 2 billion of its 24 billion parameters per token, making it fast enough to run private, tool-calling agents directly on PCs.
That is a vendor claim. The LFM sentences do not name a quant, a VRAM size, a tok/s figure, or a GPU SKU. The sentence about GeForce RTX, Jetson, RTX Spark, and DGX Spark in that section is about Nemotron Bolt E4B, not about LFM. This page does not move that hardware list onto LFM2.5-24B-A2B. “On PCs” is not a 16 GB result.
Which runtimes document support?
llama.cpp. The model card lists it. The GGUF card’s example is llama-cli -hf LiquidAI/LFM2.5-24B-A2B-GGUF with temperature 0.1, top_k 50, and repeat penalty 1.05. It says each GGUF carries those as general.sampling.* metadata and that llama.cpp applies them by default. Liquid’s docs repeat a llama-cli command and do not pin a llama.cpp tag. The first tag that loads this 128,000-token vocabulary was not stated on the card or on that docs page. Support is documented. A minimum build is not.
Ollama. The model card’s runtime table does not name Ollama. Liquid’s quick-start tabs on the docs page read on 22 October 2026 are Transformers, llama.cpp, MLX, vLLM, and SGLang. Ollama’s own library does list the model. The tags page, read 22 October 2026, shows lfm2.5:24b and lfm2.5:24b-a2b-q4_K_M at a displayed 15 GB, both digest 00a755688d0f, with a “128K context window” label. lfm2.5:24b-a2b-q4_0 displays 14 GB. lfm2.5:24b-a2b-q8_0 displays 25 GB. A lfm2.5:24b-a2b-bf16 tag is on the page. Its displayed size was not in the text returned for that row. The page dates those 24B tags as “1 week ago” and does not print a calendar day, so this page does not convert that into a date.
The lfm2.5:24b model blob shows general.architecture lfm2moe, general.file_type Q4_K_M, lfm2moe.context_length 131072, lfm2moe.block_count 40, lfm2moe.expert_count 64, lfm2moe.expert_used_count 4, and tokenizer.ggml vocab size 128000. Those fields match the card and config.json. The blob page does not print a byte size. Ollama’s displayed 15 GB is not the 14.526 GB official Q4_K_M file size. This page does not treat them as one measurement. No minimum Ollama version was stated on the card or the Liquid docs page read here.
The runtime comparison for choosing a loader is Ollama vs llama.cpp vs vLLM. Nothing on that page is an LFM2.5 bench.
MLX. Official 4-bit, 5-bit, 6-bit, 8-bit, and bf16 repos exist, with the shard sums above. Liquid’s docs require mlx-lm 0.32.0 or newer because earlier builds route experts incorrectly. That is a version pin, not a tok/s. A Mac buyer still starts from the file table and from the Mac buyer’s guide. A 16 GB Mac is in the same file cell as a 16 GB GPU. A 36 GB Mac still does not hold the 44.668 GiB BF16 file.
Also listed, without a local fit number. The card says Transformers >=5.0.0, and it lists vLLM, SGLang, ONNX, and LM Studio. The docs pin sglang>=0.5.10 for the native checkpoint. LM Studio is a name on the card with no version and no memory figure. The card’s format table still says the DSpark draft is “Coming soon.” The Hub repo LiquidAI/LFM2.5-24B-A2B-DSpark existed on 22 October 2026, with createdAt 2026-10-19. The docs describe a 328M draft and vendor throughput multiples on a B300. Those multiples are not a 16 GB or 24 GB result, and the card line and the repo do not match. This page leaves that conflict in place.
Which speeds are vendor claims?
Liquid’s card, in the edge-inference note, says the figures were collected on Pipette, Liquid’s device benchmarking setup, with llama.cpp, Q4_K_M, and a 4K-token input context. The prose numbers attached to that note are 184 tok/s on an Apple M5 Max and 114 tok/s on an AMD Ryzen AI Max+ 395, and up to 1.7× the next-best model in that comparison. The note does not name the M5 Max’s unified-memory size, the Ryzen box’s memory size, the output length, or the batch. Those three numbers are vendor claims.
The GPU note on the same card says throughput is total output tokens divided by wall time, on one NVIDIA B300, SGLang 0.5.22, 1,024 input tokens, up to 256 output tokens, BF16 weights, with the target concurrency kept full. The card says this reaches over 21K output tokens per second at high concurrency. The intro line says “up to 21K.” Both phrases are on the card. Neither is a single-stream chat speed, and neither is a 3090, 4090, or 16 GB result.
LocalRig has no first-party row. A public bench page names an RTX 3060, llama.cpp, and an Unsloth Q3 file for this model and does not print a run date. Without a date it is not a cite this page will quote. Bandwidth arithmetic that turns a file size into tok/s is not a measurement, so this page does not publish those estimates either.
The 131,072 context on the card is a maximum. Liquid’s own edge note used a 4K input. A file that fits is not a filled context window. What quantization costs covers KV in general. It does not contain an LFM2.5 KV trace.
Who this is NOT for
- Anyone treating 2.45B active as the download size. The official Q4_K_M file is 13.529 GiB. The experts are in the file.
- 8 GB and 12 GB shoppers who want an official Q4. QAD-Q4_0 is 12.646 GiB. Community IQ2 files that are under 8 GiB are a different quant.
- People who read NVIDIA’s “on PCs” as a VRAM requirement. The 21 October post names day-zero support and does not give a memory size for this model.
- Anyone copying 184 tok/s or 21K tok/s onto a 3090 or a 16 GB card. Those are Liquid’s M5 Max and B300 claims. The B300 figure is high-concurrency throughput.
- Shoppers who wanted LFM2-24B-A2B. The card distinguishes the 32K / 65K model from this 131K / 128K reasoning checkpoint. This page has no file sizes for the older model.
- A commercial deployment that has not read the license. See the next section. The threshold is a legal condition, not a hardware one.
What does the license allow?
The card’s license link is the LICENSE file in LiquidAI/LFM2.5-24B-A2B. The file is titled LFM Open License v1.0. It is not Apache-2.0 and it is not MIT.
Section 5 sets a Commercial Use limit. The Threshold is annual revenue of 10 million United States dollars or more. Commercial use by a legal entity that exceeds that threshold is not licensed. The threshold does not apply to a qualified non-profit’s non-commercial or research use, as the license defines those terms. Redistribution still has to carry the license. This page is not a legal opinion. Read the file before shipping a product on these weights.
Methodology
- Fit rule: a sticker of N GB is N × 2^30 bytes. A file is “under” only when its byte count is smaller. No KV estimate is added.
- Official bytes: Hugging Face tree API for
LiquidAI/LFM2.5-24B-A2B-GGUFand the five official MLX repos, 22 October 2026. MLX figures are safetensors shard sums. The 17,905,598-byte tokenizer is excluded and does not change a sticker. - Community bytes: tree API for
unsloth/LFM2.5-24B-A2B-GGUF,bartowski/LiquidAI_LFM2.5-24B-A2B-GGUF, and the twomlx-communitypreview repos, same day. The previews are a different source revision. - Architecture: model-card feature list, plus
config.jsonand the Ollamalfm2moeblob for the fields those files actually contain. 24.0B and 2.45B stay card figures. The safetensors counts stay beside them. - NVIDIA: Delgado, NVIDIA Blog, 21 October 2026. Quoted as a vendor announcement. No VRAM figure for this model was in that post.
- Speed: vendor claims only, from the model card’s edge and GPU notes. No independent dated tok/s met the cite bar. No first-party row.
- Prices: none fetched. No street price is stated.
Sources
- LiquidAI/LFM2.5-24B-A2B — card,
config.json, safetensors parameter block, and LFM Open License v1.0. Read 22 October 2026. HubcreatedAt2026-10-12. - LiquidAI/LFM2.5-24B-A2B-GGUF — official GGUF byte sizes and
lfm2moemetadata. - Liquid docs, LFM2.5-24B-A2B —
mlx-lm>=0.32.0, llama.cpp command, no llama.cpp tag pin. Read 22 October 2026. - NVIDIA Blog, 21 October 2026 — day-zero sentence names the model. The opening Day-0 bullet does not.
- Ollama lfm2.5 tags and the 24b model blob. Displayed sizes, not byte counts. Read 22 October 2026.
- unsloth/LFM2.5-24B-A2B-GGUF and bartowski/LiquidAI_LFM2.5-24B-A2B-GGUF — community file bytes.
- Can I run Gemma 4 26B-A4B locally? — the other MoE the card compares, different file.
- Can I run Qwen 3.8 locally? — 24 GB dense default, not this model.
- Used RTX 3090 buying guide.
Frequently Asked Questions
Can I run LFM2.5-24B-A2B on 16 GB?
The official Q4_K_M file is 13.529 GiB and the official Q5_K_M file is 15.860 GiB. Both are smaller than 16 GiB. The official Q6_K file is 18.337 GiB and is larger. That comparison is the file against the sticker. KV cache and the operating system are not in the file, and LocalRig has not measured a load.
Will 8 GB or 12 GB hold an official quant?
No official GGUF and no official MLX weight sum read on 22 October 2026 is under 12 GiB. The smallest official GGUF, QAD-Q4_0, is 12.646 GiB. Some community IQ2 files are under 8 GiB. Those are different files, not the official Q4.
Does a 24 GB GPU hold Q8?
The official Q8_0 file is 23.743 GiB, which is 0.257 GiB under a 24 GiB sticker before KV cache. The BF16 and F16 files are both 44.668 GiB, over 24 GiB and over 36 GiB. A 48 GiB sticker is the first one in this check that those two files are under.
How fast is it?
Liquid's card claims 184 tok/s on an Apple M5 Max and 114 tok/s on a Ryzen AI Max+ 395 with llama.cpp, Q4_K_M, and a 4K input, plus over 21K output tok/s on one B300 at high concurrency. Those are vendor claims. The card does not state the M5 Max memory size. LocalRig has not measured tok/s.
What license is LFM2.5-24B-A2B under?
The model card points at LFM Open License v1.0. Commercial use by a legal entity at the license threshold, annual revenue of 10 million United States dollars or more, is not licensed. It is not Apache-2.0 or MIT. Read the LICENSE file on the model repo before a commercial deployment.