Can I Run GLM-4.7-Flash Locally? 30B-A3B on 24 GB, Not GLM-5.3
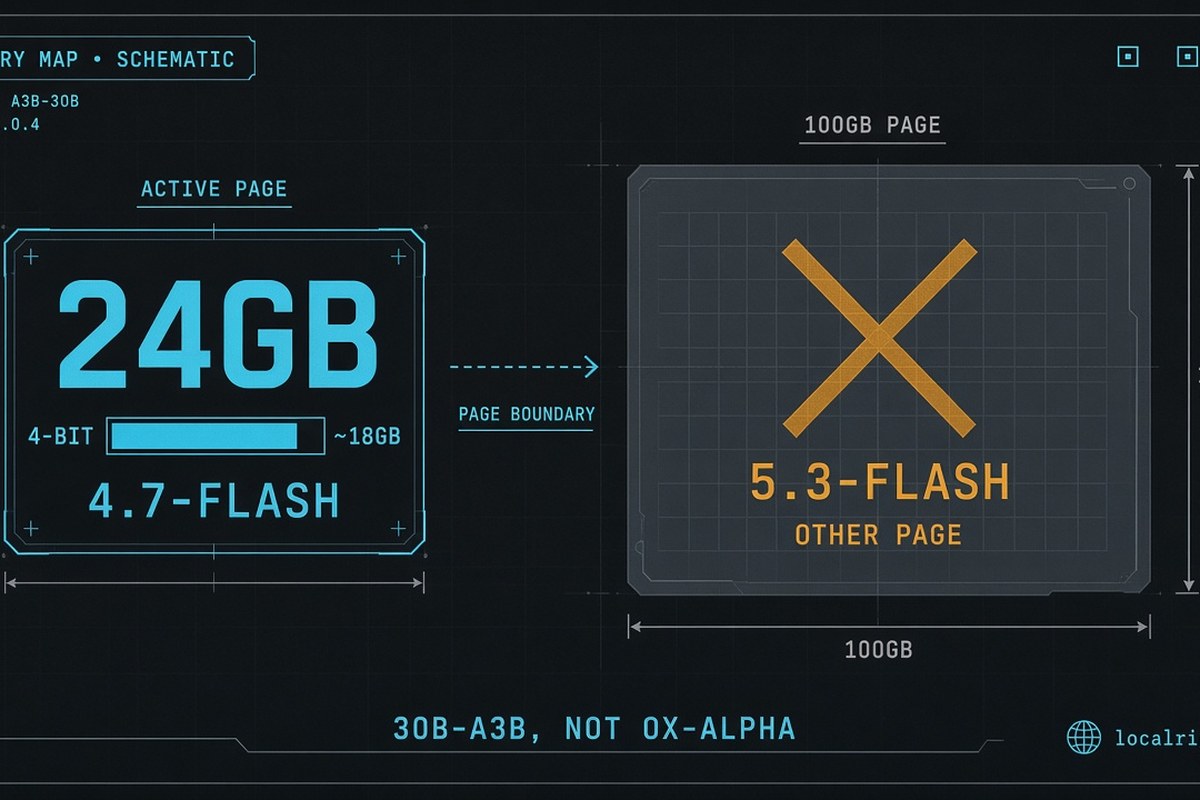
Short answer: GLM-4.7-Flash is zai-org/GLM-4.7-Flash, a 30B-A3B MoE (Hub: ~31.2B parameters, glm4_moe_lite, MIT). Unsloth (accessed 2026-09-10) says it runs on 24 GB and the 4-bit tutorial wants ~18 GB. UD-Q4_K_XL is 17.5 GB on disk. A used RTX 3090 is the LocalRig cell. This is not GLM-5.3-Flash (~100 GB 1-bit) and not GLM-5.2. LocalRig has not measured tok/s.
Do not mix 4.7-Flash, 5.3-Flash, and 5.2
4.7-Flash is the 30B-class local download. 5.3-Flash is ox-alpha at ~100 GB. 5.2 is the flagship. Unsloth’s 4.7-Flash tutorial: 200K context, 4-bit ~18 GB, 24 GB to run, 32 GB full precision. Official GGUF README: 30B-A3B, Jan 21 llama.cpp looping fix (re-download). Hub ~13.1M downloads (2026-09-10) — volume, not a rank vs Qwen 3.8 27B.
Official vLLM example on the card uses --tensor-parallel-size 4. That is a serving recipe, not a 3090 one-liner. Home path Unsloth documents is llama.cpp GGUF.
GGUF file sizes (Hub ls, 2026-09-10)
unsloth/GLM-4.7-Flash-GGUF:
| Quant | File size |
|---|---|
| UD-IQ1_S | 9.2 GB |
| UD-Q2_K_XL | 11.9 GB |
| UD-IQ3_XXS | 12.9 GB |
| UD-Q4_K_XL | 17.5 GB |
| Q4_K_M | 18.3 GB |
| UD-Q5_K_XL | 21.7 GB |
| Q6_K | 24.7 GB |
| Q8_0 | 31.8 GB |
Unsloth 4-bit tutorial ≈ 18 GB total memory. Q6_K 24.7 GB is already a 24 GB card with no KV spare. Q8_0 31.8 GB needs more than one 3090. Context in their llama-cli snippet: 16384, with a note you can raise toward 200K as RAM allows — not a filled-200k 3090 packet.
Sampling: general --temp 1.0 --top-p 0.95; tool-calling --temp 0.7 --top-p 1.0; llama.cpp --min-p 0.01; repeat penalty off (--repeat-penalty 1.0).
Used 3090 vs 16 GB
24 GB is Unsloth’s stated run class. 16 GB is under the 17.5 GB 4-bit file plus KV. A 16 GB card can load smaller UD-Q3 / Q2 files; that is a different quality band. The LocalRig used-card cell for the 4-bit Unsloth path is the 3090.
Browse used RTX 3090 24GB on eBay →
Check RTX 4060 Ti 16GB on Amazon → only for smaller quants, not Unsloth’s 18 GB 4-bit tutorial.
Rent: RunPod, Vast.ai, GPUMart.
4.7-Flash on 24 GB vs the rest of the GLM stack
This is the GLM Flash that actually matches a used 3090. GLM-5.3-Flash is 320B-A18B; Unsloth’s 1-bit band is ~100 GB. GLM-5.2 is the 1M-context flagship that LocalRig already treats as 256 GB-class. Downloading 5.3 or 5.2 because this URL said “Flash” is the failure mode.
Unsloth’s 4.7-Flash llama.cpp path (accessed 2026-09-10): -hf unsloth/GLM-4.7-Flash-GGUF:UD-Q4_K_XL, --ctx-size 16384, temp 1.0 / top_p 0.95 / min_p 0.01, repeat penalty disabled. They note you can raise context toward 200K as RAM allows. That is not a filled-200k 3090 packet. Q6_K at 24.7 GB already fills the card before KV. Stay on UD-Q4_K_XL (17.5 GB) or Q4_K_M (18.3 GB) on one 24 GB GPU.
Official vLLM/SGLang examples on the card use --tensor-parallel-size 4 / --tp-size 4. Those are multi-GPU serving recipes, often on main-branch nightlies. They are not a 3090 how-to. If you want vLLM, rent a 4-GPU node; do not assume vllm serve on one 3090 matches Unsloth’s 18 GB GGUF story.
Jan 21, 2026 Unsloth note: llama.cpp had a looping bug; they updated GGUFs — re-download. Old files are a quality shortfall, not a VRAM change.
Vendor SWE-bench 59.2 and AIME 91.6 on the GGUF README are Z.ai quality tables, not 3090 tok/s. Do not write “59 tok/s.” Compared with Qwen 3.8 27B, 4.7-Flash is a 30B-A3B MoE on the same 24 GB class. LocalRig’s dense default remains 3.8 27B; 4.7-Flash is the GLM 24 GB Flash option.
Used RTX 3090 buying guide. Ollama vs llama.cpp vs vLLM.
MXFP4_MOE on the Unsloth repo is 17.0 GB — another 24 GB-class file, not a 16 GB promise after KV. If you see “3.6B parameters” in Unsloth’s tutorial intro, that is the active scale (A3B / ~3B active), not a 3.6B dense GGUF. Hub lists ~31.2B total. Mixing “3.6B” with 7 GB Q4 math is the same class of error this site already made on DeepSeek Flash.
200K context on the tutorial is a maximum. Their llama-cli example uses 16384. A 24 GB card at 17.5 GB weights has ~6 GB for KV, runtime, and fragmentation. That is a short-to-medium window, not a filled 200k LocalRig cell. If you need 200k on 24 GB, that work already exists for Qwen 3.8 27B — a different SKU with its own KV caveats.
Fine-tuning: Unsloth says 16-bit LoRA on 4.7-Flash wants ~60 GB VRAM and transformers v5. That is a training floor, not the inference 18 GB 4-bit path. Do not buy a 3090 for LoRA on this SKU.
Chinese+English on the card is a product fact, not extra VRAM. MIT license.
Ollama: Unsloth’s 4.7-Flash tutorial is llama.cpp-first. LocalRig has no ollama run plus 3090 tok/s packet for this SKU. Repeat-penalty looping (Jan 21 GGUF update) is a quality bug — re-download; --repeat-penalty 1.0. Tool-calling sampling (temp 0.7, top_p 1.0) is a different flag set from general chat, not a second GGUF.
The 24 GB GLM Flash in this batch is this SKU. GLM-5.3-Flash is the ~100 GB 1-bit ox-alpha page. GLM-5.2 is the flagship skip. Do not shop those two URLs for a used 3090. If the card is already the daily driver for Qwen 3.8 27B, 4.7-Flash is a same-class MoE guest with more KV spare than Ornith 35B Q4 at 22.3 GB.
Who this is NOT for
- Anyone who opened this page meaning GLM-5.3-Flash. That SKU does not fit a 3090. Use the 5.3 selector.
- GLM-5.2 shoppers. Already covered; do not duplicate.
- Q8-on-one-3090 buyers. 31.8 GB file.
- Readers who need LocalRig tok/s. Vendor AIME/SWE tables are not 3090 speed.
- People skipping Qwen 3.8 27B because 4.7-Flash has more Hub downloads. Different models; 27B remains the dense default.
Methodology
- Fit numbers: Unsloth tutorial (18 GB 4-bit, 24 GB run) plus Hub ls file sizes, 2026-09-10.
- SKU identity:
zai-org/GLM-4.7-FlashHub MCP (~31.2B, glm4_moe_lite); GGUF README 30B-A3B. - Speed: none first-party.
- LocalRig first-party: none as of 2026-09-10.
Sources
Frequently Asked Questions
Can I run GLM-4.7-Flash on a used RTX 3090?
Unsloth says the 4-bit path wants about 18 GB and the SKU runs on 24 GB RAM/VRAM/unified. UD-Q4_K_XL is 17.5 GB on disk. A 24 GB 3090 is the consumer cell. LocalRig has no first-party tok/s.
Is GLM-4.7-Flash the same as GLM-5.3-Flash?
No. 4.7-Flash is 30B-A3B. 5.3-Flash is a 320B-A18B 128 GB-class SKU. Mixing those names is how a 24 GB shopper downloads a 100 GB file.
Is it GLM-5.2?
No. GLM-5.2 already has its own LocalRig selector. 4.7-Flash is the older 30B-class Flash.
Does Q8 fit a 3090?
Unsloth's Q8_0 GGUF is 31.8 GB. That overflows 24 GB. Stay at 4-bit on one card or add memory.
How fast is it?
LocalRig has no first-party row. Vendor SWE-bench and AIME tables are quality, not 3090 tok/s.