Qwen 3.8 27B Q4 at 200k: Spark, Mac 128, or Dual 3090?
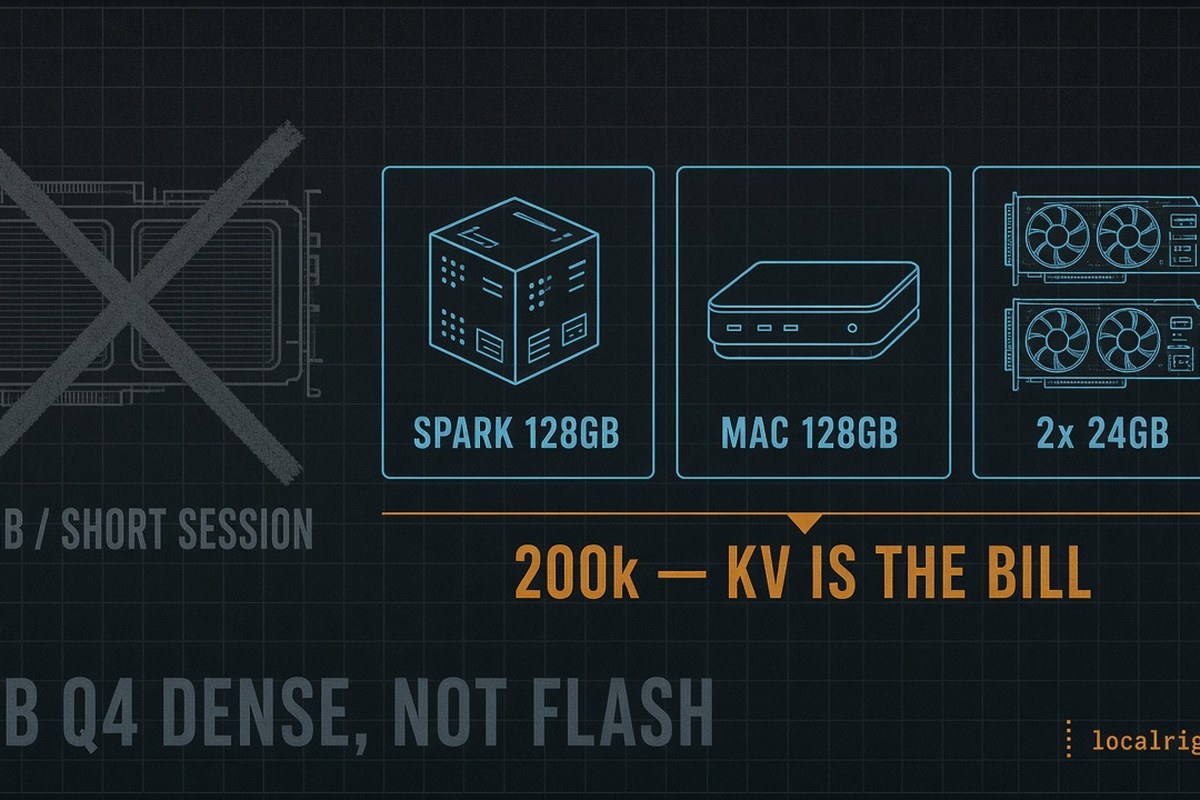
Short answer: Qwen3.8-27B Q4 at 200,000 tokens is not a used-3090 default. One 24 GB card is the short-session path. The 200k window is Spark 128 GB unified, a Mac with 128 GB unified memory, or two 24 GB cards. KV cache, not the 15–18 GB weight file, is the bill.
LocalRig’s homepage instrument defaults to this window because long-running agents and coding sessions actually use it. The instrument’s generic KV estimator is conservative on purpose. This page is the named cell for this model at that window.
LocalRig has no first-party Qwen 3.8 row. Every tok/s below is community-cited. Do not average the rows.
What 200k actually costs on this SKU
Unsloth documents Qwen3.8-27B native context as 262,144 tokens (extendable to 1M via YaRN) and 4-bit weights at 16–19 GB of RAM/VRAM (docs, accessed 2026-09-10). Those weight bands are before a long KV cache.
Qwen3.8-27B is hybrid attention. Of 64 layers, 16 are full attention; 48 are Gated DeltaNet and hold no per-token KV. The Hugging Face GGUF card bowmanslayer/Qwen3.8-27B-GGUF publishes the architecture math:
| KV dtype | Per token | 32k | 128k | 200k (scaled from the same 64 KiB/token) |
|---|---|---|---|---|
| f16 | 64 KiB | 2.0 GiB | 8.0 GiB | ~12.5 GiB |
| q8 | 32 KiB | 1.0 GiB | 4.0 GiB | ~6.3 GiB |
The 200k column is scaled from the published per-token figure, not a second lab measurement. A comparable dense-attention 27B would need roughly four times that KV. That is why the homepage calculator (~130 GB recommended for a generic 27B Q4 at 200k) and this SKU disagree, and why the disagreement is labeled.
Add the Q4_K_M file (~15.4 GiB on that card). A 24 GB 3090 still loses at 200k: the same card’s llama-fit-params max for Q4_K_M is 111,872 tokens, Vulkan, full offload. 200k is a different machine.
Confirm on the VRAM calculator (default 200k) and do not treat Unsloth’s 16–19 GB band as a 200k fit.
Hardware that matches the 200k window
| Path | Memory | 200k fit (this SKU) | Public speed packet | Buy path |
|---|---|---|---|---|
| 1× used RTX 3090 24 GB | 24 GB GDDR | No at published llama.cpp fitter (max 111,872 @ Q4_K_M) | Short-session tok/s only — see 3090 short-session page | Wrong default for 200k |
| 2× RTX 3090 | 48 GB split | Yes on KV arithmetic (weights ~15.4 GiB + ~12.5 GiB f16 KV) | Shortfall — no named 27B Q4 tok/s at a filled 200k on dual-3090 | Build if you already have the cards: dual-3090 guide |
| DGX Spark | 128 GB unified | Yes — recipes set --max-model-len 262144 | Spark NVFP4 serving, context reserved at 262k; decode benches are short-prompt unless a post says otherwise | Spark vs dual 3090 |
| Mac 128 GB unified | 128 GB | Yes on capacity | oMLX M4 Max 128 GB decode is a ~4k-prompt packet, not filled 200k | How much unified memory |
| RTX 5090 32 GB | 32 GB | Maybe — one named llama.cpp 262k allocation | toki_mwc, 2026-08-19, UD-Q4_K_XL, 28,167 MiB allocated; empty-context 63.7 tok/s, filled 262k 30.4 tok/s | Not the used-3090 basket |
Do not collapse Spark’s 27B NVFP4 recipes with Flash-Next. Different SKU, different GitHub runbooks.
Browse used RTX 3090 24GB on eBay → · RTX 3090 on Amazon → · DGX Spark → · Mac Studio 128 GB on Amazon →
If you do not want to own the 200k machine yet, rent a 32 GB+ or Spark-class hour and load the same quant: RunPod · Vast.ai · GPUMart. Those links are affiliate-tagged; they do not change the fit table.
Spark: the documented 262k serving path
Named Spark packets for 27B dense, not Flash-Next:
amasu/dgx-spark-qwen38 (accessed 2026-09-10) serves Qwen3.8-27B on one GB10 with context 262,144. Current production in that repo is SGLang + NVFP4 + DFlash2; vLLM + NVFP4 + embedded MTP is the documented rollback. Expected decode is ~24–53 tok/s depending on workload. The same README notes agentic/DeepSWE contexts growing to ~110k tokens (--allow-auto-truncate). That is a filled-context operating note, not a 200k tok/s table.
NVIDIA Developer Forum, emretoktas_openzeka, posted ~2026-09-09: 11 configs on one to four Sparks. Recipes include --max-model-len 262144 and --kv-cache-dtype fp8. The published tok/s uses 128 tokens in / 128 tokens out. Treat it as allocated 262k, measured short. Selected rows:
| Config | Runtime | TPS @ C1 (128/128) |
|---|---|---|
| BF16, TP=1, vLLM official | vLLM | 4.5 |
| NVFP4 (InferAct) + MTP n=3, TP=1 | vLLM | 18.5 |
| NVFP4 (RadixArk) + DSpark, TP=1 | SGLang | 36.6 |
| NVFP4 + MTP, TP=2 | vLLM official | 23.4 |
| NVFP4 + DSpark, TP=2 | SGLang | 51.8 |
Community-cited. Not LocalRig-measured. Unsloth’s own NVFP4 batch table is on B200, not Spark and not a 3090. Ampere 3090 buyers stay on GGUF; Spark buyers can use the NVFP4 stack.
Mac 128 GB: capacity yes, filled-200k tok/s shortfall
A 128 GB Mac has the capacity for 27B Q4 plus ~12.5 GiB of f16 KV. That is not a tok/s claim.
The named Apple packet in hand is Weschera/Qwen3.8-27B-oMLX-MTP-Mac: M4 Max, 128 GB, oMLX, native MTP. Published decode 53.3 tok/s prose / 72.1 tok/s code is from ~4k-token prompts, three reps. The settings blob may set context_window: 262144. That is a reservation, not a filled-200k measurement. LocalRig does not invent a Mac 200k number from that row.
bowmanslayer’s Metal row is a different machine: M1 Max 64 GB, llama.cpp, 512-token greedy, 11.17 tok/s with no draft; MLX on the same box 15.9 tok/s. Still not 200k filled.
30-day Apple tok/s shortfall on the X watchlist stands. Do not substitute a remembered figure.
Dual 3090: the 48 GB fit without a 200k speed packet
Two 24 GB cards give 48 GB of split device memory. For this hybrid SKU, weights + 200k f16 KV sit near 28 GiB before runtime buffers — inside 48 GB, outside 24 GB. That is architecture arithmetic from the GGUF card, not a dual-3090 llama-bench.
Shortfall: no named public packet in this pass with URL + date + 27B Q4 + runtime + dual-3090 + filled 200k tok/s. Do not copy single-3090 41 tok/s onto a 200k dual-card agent. For the box itself see dual RTX 3090 build and Spark vs 2× 3090.
Runtime choice at this window: Ollama vs llama.cpp vs vLLM at 200k.
Who this is NOT for
- Anyone who wants LocalRig-measured 200k tok/s. There is no lab row.
- Buyers whose job is 4k–32k chat or a short coding paste. A used 3090 is the honest card. Do not buy Spark to fix a short-session problem.
- People downloading Flash-Next because the homepage says 200k. Wrong SKU. Stay on 27B dense or open the Flash selector.
- 1M YaRN on a 24 GB card. Native 262k is already past one 3090. 1M is cluster, rent, or a documented Spark recipe that actually enables YaRN. amasu notes DFlash2 is not YaRN-compatible.
- Anyone treating empty-context tok/s as a filled-repo agent. toki_mwc’s 5090 row is the warning: 63.7 tok/s empty vs 30.4 tok/s at filled 262k, plus a 4 m 27 s prefill.
Methodology
- Fit / KV: Unsloth 4-bit 16–19 GB (weights). bowmanslayer GGUF card: 64 KiB/token f16, llama-fit-params max context on one RTX 3090. 200k KV scaled from that per-token figure.
- Spark: amasu/dgx-spark-qwen38 (context 262144; expected ~24–53 tok/s by workload) and NVIDIA forum 11-config study (~2026-09-09), 128/128 bench with max-model-len 262144. Community / operator-reported.
- Mac: Weschera oMLX M4 Max 128 GB at ~4k prompts; bowmanslayer Metal M1 Max 64 GB at 512 tokens. Filled-200k Mac tok/s: not in packet.
- 5090 long context: toki_mwc, 2026-08-19, llama.cpp b10430 CUDA, UD-Q4_K_XL, 262,144. Community-cited.
- LocalRig first-party: none for Qwen 3.8 as of 2026-09-10.
Sources
- Unsloth Qwen3.8 run guide — 4-bit 16–19 GB; native 262,144.
- bowmanslayer/Qwen3.8-27B-GGUF — 3090 Vulkan table, KV math, llama-fit-params.
- amasu/dgx-spark-qwen38 — Spark 27B NVFP4, 262k context.
- NVIDIA forum 27B Spark study — 2026-09-09.
- Ollama library qwen3.8 — 27b 18GB, 256K advertised.
- Weschera oMLX Mac recipe.
- toki_mwc 5090 262k writeup — 2026-08-19.
- Sibling cells: 27B Q4 on used 3090 · runtimes at 200k · SKU selector.
Frequently Asked Questions
Can a used RTX 3090 run Qwen 3.8 27B Q4 at 200k context?
Not as a fully GPU-resident f16-KV session. bowmanslayer's llama-fit-params on one 3090 lists a Q4_K_M max of 111,872 tokens. 200k is the next hardware class. Use the 3090 at 4k–32k instead.
Does the homepage VRAM instrument mean I need 128 GB for any 27B at 200k?
The instrument uses a conservative dense-attention KV estimator. Qwen3.8-27B only keeps KV on 16 of 64 layers, so this SKU is cheaper on cache than a generic 27B. A single 24 GB card still does not fit 200k at the published llama.cpp fitter. Spark / Mac 128 / 48 GB split remain the 200k machines.
Is 200k the same as the model's native 262k?
Same hardware class. Unsloth lists native context 262,144, extendable to 1M via YaRN. LocalRig's homepage default is 200,000 as the long-agent / repo window. Do not treat 1M as free headroom.
Does LocalRig have first-party 27B tok/s at 200k?
No. Every speed figure on this page is community-cited with URL, date, model, quant, runtime, and hardware. Not independently verified. Not an engine.db row.
Is this Flash-Next?
No. This page is Qwen3.8-27B dense Q4. Flash-Next is a different SKU and a different buy. See the 27B vs Flash selector.