Qwen 3.8 27B Q4 on a Used RTX 3090: The Short-Session Path
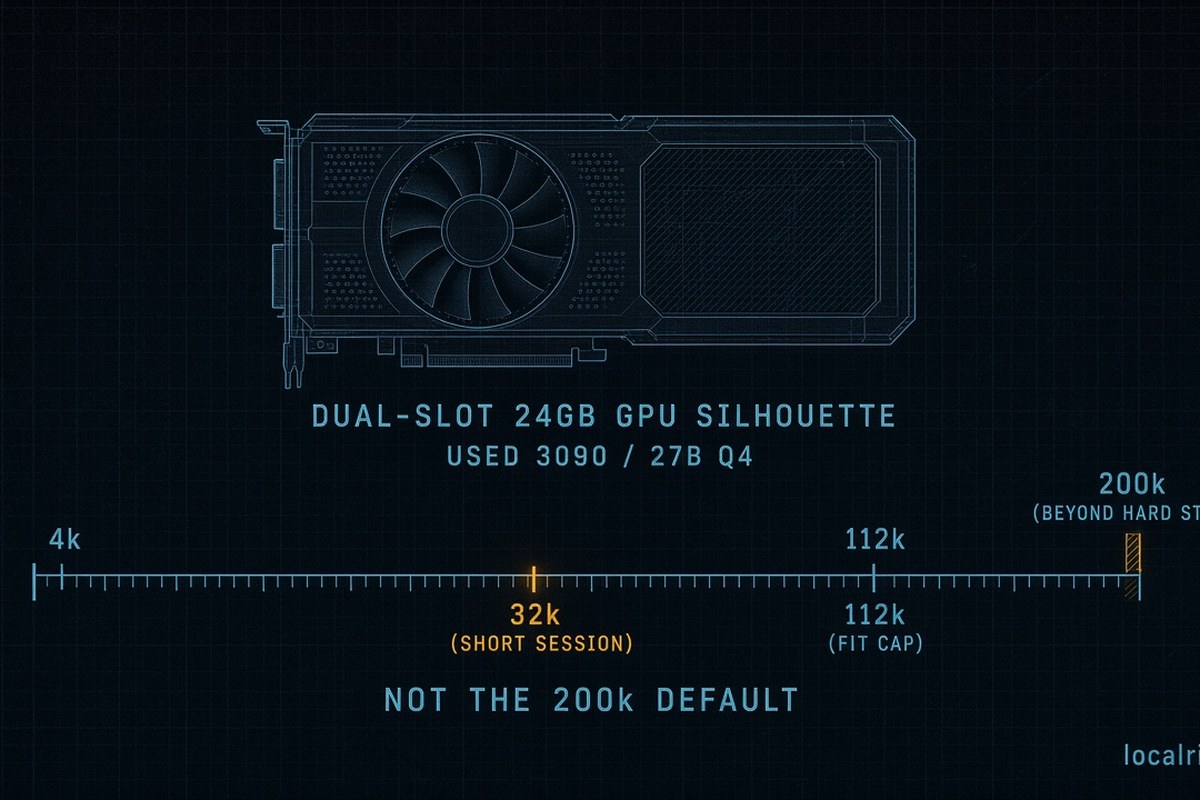
Short answer: a used RTX 3090 24 GB runs Qwen3.8-27B Q4 if the job is a short session (4,096–32,768 tokens). That is still a real buyer. It is not the homepage 200k agent default. Do not buy a second card or a Spark because a 32k paste felt slow.
This is the intersection page the SKU selector does not replace. Can I run Qwen 3.8 locally? picks 27B vs Flash-Next. This page is 27B Q4 × 3090 × 4k–32k.
LocalRig has no first-party 27B row. Speed figures are community-cited.
Does 24 GB actually fit?
Yes, at 4-bit, with context discipline. Unsloth’s hardware table (accessed 2026-09-10) puts 4-bit Qwen3.8-27B at 16–19 GB of total memory, 6-bit at 23–26 GB, and BF16 at 56 GB. MTP wants another 1–2 GB. That is why 24 GB is the buy floor: a 16 GB card can load the file and then lose the window.
Unsloth Dynamic GGUF file sizes (unsloth/Qwen3.8-27B-GGUF, accessed 2026-09-10):
| Quant | Approx. file | 12 GB? | 24 GB at 32k? |
|---|---|---|---|
| UD-IQ1_S | 6.19 GB | Emergency only | Yes; quality is the constraint |
| UD-Q3_K_XL | 13.1 GB | Almost no cache | Yes |
| UD-Q4_K_XL | 17.6 GB | No | Default |
| UD-Q5_K_M | 19.8 GB | No | Yes, less cache |
| Q8_0 | 29 GB | No | No on one 24 GB card |
bowmanslayer’s imatrix Q4_K_M is 15.4 GiB with a different recipe. Same card class. Use one file family and stay on it.
Qwen3.8-27B only caches KV on 16 of 64 layers. At f16 that is 2.0 GiB at 32k on the GGUF card — small compared with a dense-attention 27B. The 3090 still dies at 200k. llama-fit-params on that 3090 lists Q4_K_M max 111,872 tokens. 32k is comfortable. 200k is the other page.
The same card’s fit table is a quant vs window trade, not a quality ranking:
| Quant on that 3090 (Vulkan, full offload) | File | tg128 | Max context (llama-fit-params) |
|---|---|---|---|
| Q6_K | 20.6 GiB | 32.3 | 32,512 |
| Q5_K_M | 17.9 GiB | 36.9 | 73,472 |
| Q4_K_M | 15.4 GiB | 41.4 | 111,872 |
| IQ4_XS | 14.0 GiB | 31.9 | 133,632 |
Q6_K is the quality pick and the one that lands on a 32k-class cap. Q4_K_M is faster and buys 3.4× the context on the same 24 GB. IQ4_XS is smaller but ~23% slower than Q4_K_M on that card — take it for size, not speed. Those max-context figures are what fits, not a filled-window tok/s.
Browse used RTX 3090 24GB on eBay → · RTX 3090 on Amazon → · Used 3090 buying guide
Vetting, power, and mining-farm risk live on the buying guide. This page does not re-rank cards by payout.
If you do not own a 24 GB card yet, rent one and load the same GGUF: RunPod · Vast.ai · GPUMart 4090 monthly. Affiliate-tagged; they do not change the quant.
Public 3090 decode numbers (not LocalRig)
Do not average these. Backend and MTP flags move the number more than the card name.
| Source | Date | Hardware | Runtime / notes | Decode (as published) |
|---|---|---|---|---|
| bowmanslayer GGUF card | accessed 2026-09-10 | RTX 3090 24 GB | llama.cpp Vulkan, Q4_K_M, tg128, full offload | 41.4 tok/s |
| same card | accessed 2026-09-10 | RTX 3090 | llama.cpp CUDA, Q4_K_M, 512 tok, greedy, no draft (mean of 3) | 41.2 tok/s |
| same card | accessed 2026-09-10 | RTX 3090 | CUDA, --spec-draft-n-max 1, MTP | 56.1 tok/s (75% accept) |
| same card | accessed 2026-09-10 | RTX 3090 | Vulkan, n-max 1 | 40.4 tok/s (+3%) |
| sudoingX | 2026-08-30 | RTX 3090 | llama.cpp, MTP flag | 41 tok/s |
| lingster/qwen38-mtp | accessed 2026-09-07 | RTX 3090 | Q4_K_M, --spec-type draft-mtp | 31.0 → 41.3 tok/s |
bowmanslayer’s MTP table is explicit: +36% on CUDA at n-max 1, +3% on Vulkan, negative on Metal. Same files. If you attach a draft on the wrong backend, you pay for it. Requires llama.cpp b10502+ for --spec-type draft-mtp.
pp512 on that Vulkan Q4_K_M row is 1183 tok/s. That is prompt processing, not decode. Do not paste it into an agent-latency argument.
Older llama.cpp builds fail with unknown model architecture: 'qwen35' or a missing blk.64 tensor. That is a converter/runtime problem, not a VRAM problem. Unsloth’s documented load:
hf download unsloth/Qwen3.8-27B-GGUF \
    --local-dir unsloth/Qwen3.8-27B-GGUF \
    --include "*UD-Q4_K_XL*"

./llama.cpp/llama-cli \
    --model unsloth/Qwen3.8-27B-GGUF/Qwen3.8-27B-UD-Q4_K_XL.gguf \
    --temp 1.0 --top-p 0.95 --top-k 20 --min-p 0.0
Step-by-step CUDA build: run llama.cpp on RTX 3090. Pin context with -c 8192 or -c 32768 until you have measured VRAM headroom. Do not pass 262144 on this card because the model card printed it.
Ollama’s library lists qwen3.8:27b at 18 GB with 256K advertised. Advertised native window ≠ allocated num-ctx on 24 GB. Raise context only when the task needs it. Runtime comparison at the long window: Ollama vs llama.cpp vs vLLM at 200k.
What a 3090 is for, and what it is not
For: daily 27B Q4 instruct/thinking at 4k–32k, local coding pastes that fit a short session, vision with the separate mmproj if you have a couple of gigabytes left, MTP on CUDA if the build is new enough.
Not for: a repo-scale agent at 128k–200k. Hybrid KV is small, not free. One 3090’s published fit cap is ~112k at Q4_K_M. The homepage 200k default maps to Spark / Mac 128 / dual-3090.
CUDA OOM on this card is usually context or MTP headroom, not a bad GGUF. Drop -c before you drop to Q3. Practical flags: fix Ollama CUDA OOM. Sustained 350 W-class load is a PSU/cooling problem, not a VRAM table: PSU for multi-GPU if you later add a second 3090.
A 4090 does not add VRAM. analogalok’s 4090 27B MTP 65 tok/s (2026-08-14) is a different card and a different post. Speed, not fit. See the SKU selector’s public table if you are shopping Ada.
NVFP4 is Blackwell (50-series, Spark, B200). A 3090 stays on GGUF.
Who this is NOT for
- 200k / 262k agent buyers. Wrong cell. Read the 200k hardware page.
- Anyone who wants a LocalRig lab number. Cite the row or run it on silicon you already own.
- 16 GB shoppers expecting 32k with Q4_K_M. The GGUF card says that quant leaves almost no KV on 16 GB. IQ4_XS is the 16 GB estimate, not a 3090 measurement.
- Flash-Next shoppers. 75 GB GGUF / Spark NVFP4. Not this card. Flash selector.
- Production multi-user serving on one 24 GB card. Fit is not a scheduler. vLLM multi-GPU.
Methodology
- Weights: Unsloth 4-bit 16–19 GB table and HF file sizes, accessed 2026-09-10. Vendor estimates.
- Fit cap: bowmanslayer
llama-fit-paramson one RTX 3090, Vulkan, full offload. What fits, not a calculation. - Decode: bowmanslayer CUDA/Vulkan MTP tables (512-token greedy unless noted); sudoingX 2026-08-30; lingster paired A/B. Community-cited. Not LocalRig-measured.
- Context default on this page: 4k–32k as LocalRig’s short-session band. 200k is out of scope.
- LocalRig first-party: none for Qwen 3.8 as of 2026-09-10.
Sources
Frequently Asked Questions
Can a used RTX 3090 run Qwen 3.8 27B Q4?
Yes at a 4-bit GGUF for a short session. Unsloth lists 4-bit 27B at 16–19 GB before long context and MTP. A 24 GB 3090 is the buy floor because KV and MTP need headroom. LocalRig has not measured tok/s on this card.
What context length actually fits on one 3090?
bowmanslayer's llama-fit-params on one 3090, Vulkan, Q4_K_M, lists a maximum of 111,872 tokens. 32,768 is the short-session window. 200k does not fit that fitter. See the 200k hardware page.
Is 41 tok/s a LocalRig number?
No. sudoingX (2026-08-30) and bowmanslayer (CUDA no-draft 41.2; Vulkan tg128 41.4) are community-cited. Stack and backend change the number. Vulkan MTP barely helps; CUDA MTP at n-max 1 is 56.1 tok/s on that card.
Should I use a 16 GB card instead?
Unsloth says 4-bit 27B can load on 16–19 GB. The same GGUF card says Q4_K_M on 16 GB leaves almost nothing for KV; IQ4_XS is the 16 GB pick, estimated not measured. LocalRig still calls 24 GB the buy floor.
Is this the homepage default?
The homepage model is 27B. The homepage context default is 200k, which is Spark / Mac 128 / dual-3090. This page is the honest 4k–32k 3090 cell.