Can I Run Qwen 3.8 Flash Locally? 75 GB GGUF, Not the 27B Homepage SKU
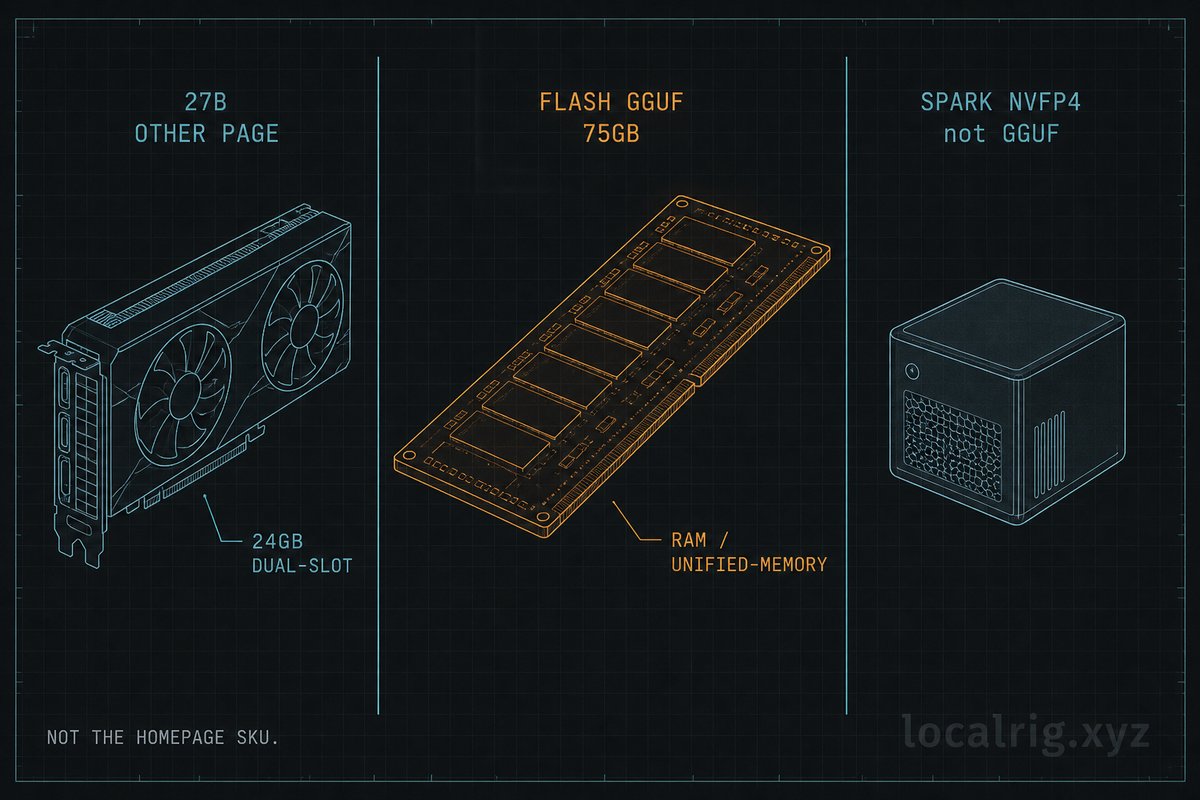
Short answer: Qwen 3.8 Flash is the 75 GB-class MoE, not the 27B dense model on the homepage. Unsloth publishes this GGUF as Qwen3.8-Flash-Next: 1-bit 75 GB, and they tell you to bring a 96 GB RAM or unified-memory machine (docs, accessed 2026-09-07). A used 3090 is the wrong default. DGX Spark NVFP4 (Mia / vLLM) is a different stack with different published tok/s. LocalRig has not measured this SKU.
The 27B selector stays at Can I run Qwen 3.8 locally?. This page exists so Flash does not get stuffed into that 24 GB table.
Is this the same download as Qwen3.8-27B?
No. Pick the SKU first. 27B is dense, Unsloth 4-bit 16–19 GB, 24 GB buy floor. Flash-class GGUF is a 125B MoE (Unsloth: Qwen3.8-Flash-Next, Qwen4 architecture, 262K context). The 1-bit file is large because Unsloth says Ngram / PLE layers stay at a milder quant.
September 2026 X traffic used “Flash” and “Flash-Next” in the same sentence. LocalRig’s split for buyers:
| Name you saw | What this page treats it as | Machine class |
|---|---|---|
| Qwen3.8-27B | Dense daily driver | 24 GB used 3090 / 4090 — other article |
| Flash GGUF / Unsloth Flash-Next GGUF | 125B MoE, 75 GB at 1-bit | 96 GB RAM / unified, or 80 GB GPU with 1-bit only |
| Flash-Next on Spark (Mia) | vLLM NVFP4 on DGX Spark | Spark appliance — Spark vs dual-3090 |
| Qwen3.8-2.4T | Giant MoE | Do not buy home hardware |
This article covers the middle row. It is intentionally not on the LocalRig homepage. The homepage instrument stays 27B.
How much RAM or VRAM does the GGUF need?
75 GB at 1-bit; Unsloth prefers 96 GB in the machine. Their table is total memory (RAM + VRAM, or unified). Copied 2026-09-07:
| Quant band (Unsloth) | Total memory they list |
|---|---|
| 1-bit | 75 GB |
| 2-bit | 79 GB |
| 3-bit | 90 GB |
| 4-bit | 96–114 GB |
| 5-bit | 163 GB |
| 8-bit | 200 GB |
| BF16 | 355 GB |
KLD / file-size table on the same page (vendor, not LocalRig): UD-IQ1_S 72.5 GB, UD-IQ1_M 74.5 GB, UD-Q2_K_XL 78.9 GB, UD-Q4_K_XL 111.3 GB. MTP wants 1–2 GB extra. Their MTP hardware table nudges 1-bit to 76 GB and 3-bit MTP to 91 GB — still a 96 GB-class box.
A 24 GB card does not hold 75 GB of weights. Offloading layers into system RAM is a different config (see analogalok below). Do not advertise “runs on a 4090” without saying plus ~100 GB host RAM.
Weights: unsloth/Qwen3.8-Flash-Next-GGUF.
Can I use a 24 GB 4090 if I have a lot of system RAM?
As an offload experiment, some people have. As a “buy a 4090 for Flash” pitch, no. analogalok reported Flash-Next MoE on a 24 GB 4090 plus system RAM at 21 tok/s decode and 364 t/s prefill, no MTP, in a quoted thread dated 2026-08-26 (post). That is a named community config, not a LocalRig measurement, and it is not Unsloth’s 170 tok/s RTX PRO 6000 figure.
If you only own 24 GB of VRAM and you want a usable daily driver, stay on 27B Q4. Buy a used 3090 for that SKU, not for Flash.
Browse used RTX 3090 24GB on eBay → · Used 3090 buying guide →
What public speed numbers exist, and on which GPUs?
Vendor: 170 tok/s on 1× RTX PRO 6000 with MTP. Community offload: 21 tok/s on 4090+RAM. Spark NVFP4 is another column.
Unsloth’s MTP guide (accessed 2026-09-07) says Flash-Next GGUF reaches 170 tokens/s on 1× RTX 6000 PRO versus a 100 tok/s baseline, with MTP described as 1.3–1.7× and “especially effective on GPUs.” RTX PRO 6000 is a 96 GB-class workstation GPU, not a 3090. Gains on “older Macs” are described as smaller because of memory bandwidth.
Spark numbers from Mia are vLLM NVFP4, not this GGUF table: ~47 tok/s prose on one Spark (2026-09-06) and dual-Spark follow-ups the same week. Runbooks: single Spark, dual Spark. Cite them on the Spark comparison page; do not paste them into a 4090 column.
None of these rows is a LocalRig lab hour.
Should I rent an 80 GB A100 to try 1-bit?
1-bit (~75 GB) is the only Unsloth band that has a chance on a single 80 GB GPU, and even then KV + MTP eat the margin. 4-bit at 96–114 GB does not fit one 80 GB card. That is the honest Vultr / Lambda / other IaaS try path: datacenter A100/H100, not a marketplace 4090.
Check Vultr GPU Cloud for current A100/H100 inventory. Vultr does not rent consumer 4090/3090 cards. For 24 GB GGUF experiments (27B, not this SKU), use RunPod or Vast.ai. Positioning: Vultr GPU cloud review · H100 rental comparison.
A 128 GB Mac or DGX Spark matches Unsloth’s “large unified memory” language more cleanly than hoping an 80 GB rental leaves room for a long window.
How do I load the GGUF if the machine fits?
Unsloth documents Unsloth Desktop (MTP on by default in that app) and llama.cpp. Their example unsloth run line uses UD-Q4_K_XL — remember that 4-bit is the 96–114 GB band, not the 75 GB 1-bit band. For 1-bit, download UD-IQ1_S / UD-IQ1_M from the same repo.
Vendor llama.cpp sketch (accessed 2026-09-07; confirm filenames on Hugging Face):
hf download unsloth/Qwen3.8-Flash-Next-GGUF \
    --local-dir unsloth/Qwen3.8-Flash-Next-GGUF \
    --include "*UD-IQ1_M*"

./llama.cpp/llama-cli \
    --model unsloth/Qwen3.8-Flash-Next-GGUF/UD-IQ1_M/Qwen3.8-Flash-Next-UD-IQ1_M.gguf \
    --temp 1.0 --top-p 0.95 --top-k 20 --min-p 0.0
Thinking vs instruct sampling differs in Unsloth’s table: thinking temp=1.0 / top_p=0.95; instruct temp=0.7 / top_p=0.80 plus presence_penalty=1.5. MTP on llama.cpp uses their qwen4exp/mtp fork plus a draft GGUF (--spec-type draft-mtp). That is vendor procedure. Old Ollama builds will not magically grow 75 GB of VRAM.
Related: Ollama vs llama.cpp vs vLLM. Dual-Spark how-to: Dual DGX Spark for Qwen 3.8 Flash-Next.
Filled-context runtime cell: shortfall. analogalok’s 4090+RAM offload (21 tok/s decode, 2026-08-26) does not pin filled 200k. Mia’s Spark NVFP4 posts are a different stack from Unsloth’s 75 GB GGUF and do not pin filled 200k GGUF tok/s. Unsloth’s 170 tok/s is 1× RTX PRO 6000 with MTP. LocalRig will not invent an Ollama vs llama.cpp vs vLLM triangle for filled-200k Flash-Next. Empty cells stay empty.
Who this is NOT for
- Anyone who wants this SKU on the LocalRig homepage. Homepage stays Qwen 3.8 27B.
- Buyers who think Flash is a 24 GB GGUF. 75 GB at 1-bit is the vendor floor.
- Anyone copying Unsloth’s 170 tok/s onto a 3090. That figure is 1× RTX PRO 6000 with MTP.
- People mixing analogalok’s 21 tok/s offload run with Mia’s Spark NVFP4 numbers. Different hardware, different runtime.
- Shoppers using Unsloth’s “beats Opus” marketing as a VRAM requirement. Quality claims are not fit math.
- Anyone expecting LocalRig first-party tok/s. None as of 2026-09-10.
- Readers looking for a filled-200k Flash-Next runtime page. No cite packet; no article.
Methodology
- Fit numbers: Unsloth Qwen3.8-Flash-Next hardware table and KLD/file-size table, accessed 2026-09-07. Vendor estimates, total RAM+VRAM or unified memory.
- Speed numbers: Unsloth MTP claim (170 vs 100 tok/s on 1× RTX PRO 6000); analogalok 2026-08-26 4090+RAM offload (21 / 364, no MTP); Mia Spark vLLM NVFP4 posts 2026-09-04–2026-09-06. None are LocalRig-measured. Each row keeps its hardware and runtime label.
- SKU naming: Unsloth’s published GGUF for this memory class is labeled Flash-Next. This page uses “Flash” in the title because that is the buyer query; the download name is the Hugging Face repo above.
- LocalRig first-party: none. No
engine.dbrow. Not a thin model×hardware matrix page.
Sources
- Unsloth Qwen3.8-Flash-Next guide — 75 GB / 96 GB table, MTP 170 tok/s on RTX PRO 6000.
- unsloth/Qwen3.8-Flash-Next-GGUF.
- analogalok, 2026-08-26: https://x.com/analogalok/status/2092697021790708148
- Mia Spark NVFP4: https://x.com/MiaAI_lab/status/2096601527456592223 and GitHub runbooks linked above.
- Qwen 3.8 27B selector — the 24 GB SKU.
- Vultr GPU Cloud — 80 GB-class try path, not a 4090.
Frequently Asked Questions
Can I run Qwen 3.8 Flash on a used RTX 3090?
Not as a full-GPU load. Unsloth's smallest 1-bit GGUF is about 75 GB of total memory and they recommend a 96 GB machine. A 24 GB 3090 can only participate as a partial offload device. For a 3090 daily driver, use Qwen3.8-27B Q4 instead.
Is Qwen 3.8 Flash the same as Qwen 3.8 27B?
No. 27B is the dense vision-language SKU that maps to 24 GB cards and to the LocalRig homepage instrument. Flash / Flash-Next GGUF is a 125B MoE that Unsloth sizes at 75 GB (1-bit). Different download, different machine.
Is Unsloth's Flash-Next GGUF the same as Mia's Spark NVFP4 stack?
Same family name, different serving stack. Unsloth's GGUF path is llama.cpp / Unsloth Desktop on large RAM or unified memory. Mia's published Spark numbers are vLLM NVFP4 on DGX Spark. Do not mix the tok/s columns.
Will an 80 GB A100 hold the 1-bit GGUF?
Unsloth's 1-bit band is 75 GB, so a single 80 GB A100 is a tight fit-check for weights plus a little KV, not for long context plus MTP. 4-bit in their table is 96–114 GB and does not fit one 80 GB GPU. Verify live datacenter inventory; do not assume 4-bit.
Does LocalRig have first-party Flash tok/s?
No. Speed figures on this page are Unsloth vendor tables or named X posts, dated, with hardware labeled. This SKU is also kept off the LocalRig homepage on purpose.