Can I Run Gemma 4 31B Locally? Unsloth 4-bit 17–20 GB on a 24 GB Card
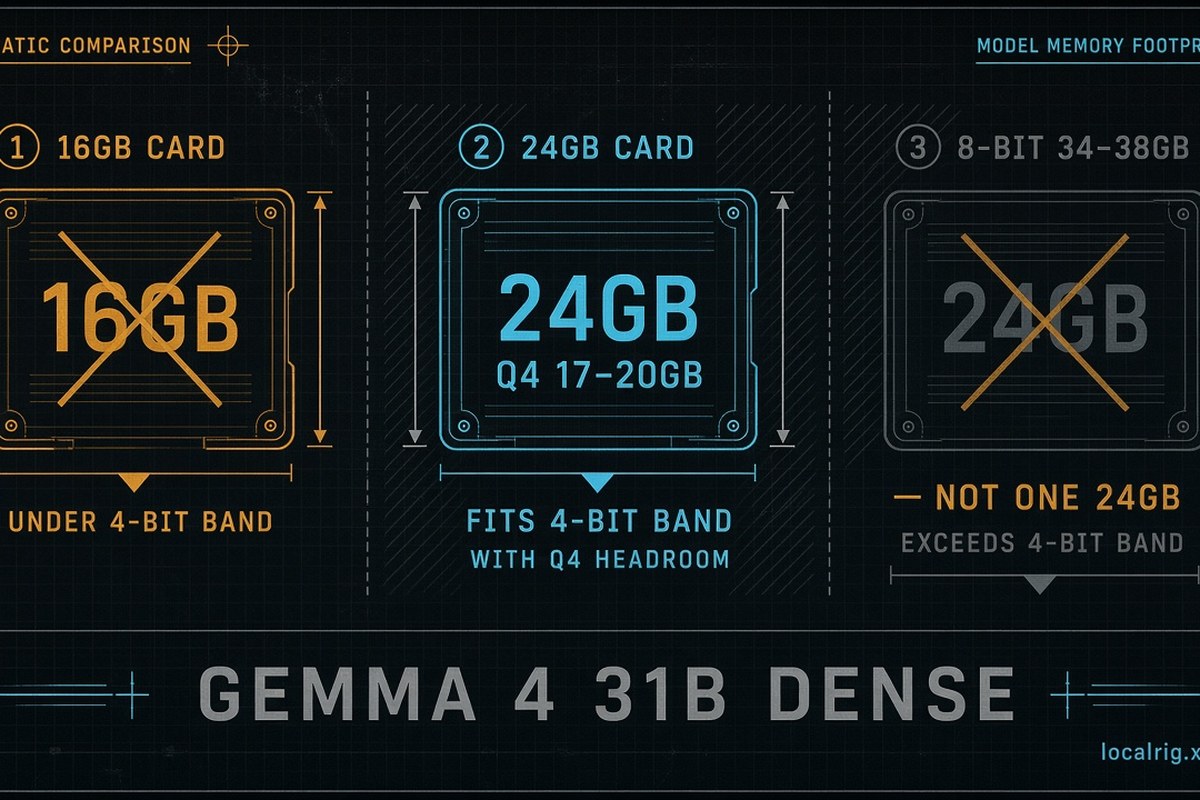
Short answer: google/gemma-4-31B-it is a ~31B dense instruction SKU (Hub: 31.27B parameters, Apache-2.0, 256K context, text+image). Unsloth’s Gemma 4 table (accessed 2026-09-10) wants 17–20 GB total memory at 4-bit, 34–38 GB at 8-bit, 62 GB at BF16. A used RTX 3090 (24 GB) is the LocalRig cell for 4-bit. A 16 GB card sits under that 4-bit band. This is not Gemma 4 26B-A4B. LocalRig has not measured tok/s.
31B dense vs 26B-A4B — which download?
Different architectures. Unsloth: 26B-A4B is MoE (4B active), “best speed/quality tradeoff”; 31B is dense, “strongest performance at slower inference.” Official family card: 31B dense, 60 layers, 256K, ~550M vision encoder, text+image (no native audio on 31B). 26B-A4B is the other LocalRig selector.
Hub (2026-09-10): google/gemma-4-31B-it ~56M downloads. Volume is not a LocalRig ranking against Qwen 3.8 27B.
QAT variants exist (Unsloth: ~3× memory cut). This page sizes the standard GGUF bands in Unsloth’s hardware table, not every QAT SKU.
Unsloth memory table (Gemma 4 family excerpt)
Copied 2026-09-10. Units = RAM + VRAM or unified memory.
| Variant | 4-bit | 8-bit | BF16 / FP16 |
|---|---|---|---|
| 26B A4B | 16–18 GB | 28–30 GB | 52 GB |
| 31B | 17–20 GB | 34–38 GB | 62 GB |
Sampling Unsloth copies from Google: temperature 1.0, top_p 0.95, top_k 64. Thinking: <|think|> on the system prompt. Max context 262,144 for 31B. KV on top of the 17–20 GB 4-bit band will eat the rest of a 24 GB card. LocalRig has no filled-256k packet for 31B on a 3090.
Can a used 3090 run it? Can 16 GB?
24 GB: Unsloth 4-bit class. 16 GB: under the 17–20 GB 4-bit band. A 3090 can hold 4-bit weights with modest context. 8-bit (34–38 GB) does not fit one 24 GB card. Dual 3090 (48 GB) is the 8-bit conversation, not this page’s primary cell.
Browse used RTX 3090 24GB on eBay →
Check RTX 4060 Ti 16GB on Amazon → only if you are targeting 26B-A4B or accepting offload on 31B. Do not buy 16 GB expecting Unsloth’s 31B 4-bit band to land with spare KV.
Try-before-buy: RunPod, Vast.ai, GPUMart.
Runtime — what is documented?
llama.cpp / Unsloth GGUF is the documented home path. MTP is a separate Unsloth add-on (Jun 9, 2026). Unsloth says Gemma 4 MTP is ~1.4–2.2× faster in their Studio path. That is not a 3090 llama-bench from LocalRig. Ollama: no LocalRig library+hardware+tok/s packet for gemma-4-31B-it as of 2026-09-10. NVIDIA NVFP4 (nvidia/Gemma-4-31B-IT-NVFP4) is a different quant stack (Blackwell / Spark class) — do not mix with Unsloth GGUF on Ampere.
Related: Ollama vs llama.cpp vs vLLM. How to run LLMs locally.
What 24 GB still does not buy you on 31B
8-bit, BF16, and a filled 256K window. Unsloth’s 8-bit band is 34–38 GB. One 3090 is 24 GB. Dual 3090 (48 GB) is the first consumer split that can even talk about 8-bit, and even then KV remains extra. BF16 at 62 GB is Spark/Mac-128-or-better, or rent. The 4-bit 17–20 GB band is the only honest single-3090 story.
Vision: the official 31B-it card is image-text-to-text with a ~550M vision encoder. A GGUF without mmproj is a text-only experiment even if the base model is multimodal. Confirm the file list on unsloth/gemma-4-31B-it-GGUF before you tell a buyer “it sees screenshots.” Audio is an E2B/E4B feature in Unsloth’s family table, not 31B.
Thinking mode (<|think|>) adds tokens to the KV cache the same way other reasoning SKUs do. A 24 GB card that “fits 4-bit” at 4k can still OOM when thinking plus a repo dump fill the window. LocalRig has no 3090 llama-fit-params packet. Cap context until you measure.
QAT (Unsloth Jun 5, 2026) is a different download with a lower memory claim (~3×). Do not mix QAT file sizes into the standard 17–20 GB 4-bit row. MTP (Jun 9) is a speed path in Unsloth Studio, not a reason to size a 16 GB card.
If the job is “one used 24 GB card, dense daily driver,” Qwen 3.8 27B Q4 is still the LocalRig default. Gemma 4 31B is the Gemma dense option on that same card class at Unsloth’s 17–20 GB 4-bit band. 26B-A4B is the MoE alternative if you want Unsloth’s slightly lower 16–18 GB 4-bit floor and 4B active.
Best GPU for local LLM still starts with VRAM-per-dollar, not Hub download counts. Gemma 4 31B’s ~56M Hub downloads (2026-09-10) do not change the 17–20 GB band.
Apache-2.0 on the official card is the license shoppers actually care about for commercial local use. That does not change VRAM. A Mac with 32 GB unified memory sits in Unsloth’s 8-bit conversation (34–38 GB) only if you offload; 4-bit 17–20 GB is closer to a 24 GB discrete card than to a 16 GB laptop GPU. Apple Silicon still has the prompt-processing tax documented in why prompt processing is slow on Mac — LocalRig has no Gemma 4 31B Metal tok/s to quote, so the Mac path is “weights may load at 4-bit on 32 GB unified, speed unknown.”
If you are renting to decide between 31B dense and 26B-A4B, use the same 24 GB pod for both Unsloth GGUFs rather than jumping to an H100. Vultr is the wrong catalog for that experiment (no consumer 4090/3090). RunPod, Vast, and GPUMart are the 24 GB rental lanes.
Who this is NOT for
- Shoppers who grabbed 26B-A4B files while reading this 31B URL. Different MoE vs dense math.
- 16 GB buyers who need Unsloth’s 17–20 GB 4-bit band plus KV. Wrong card class unless you offload and accept the shortfall.
- Anyone who needs LocalRig tok/s or a filled-256k 3090 number. Neither exists here.
- People treating Hub download counts as a reason to skip Qwen 3.8 27B. Different daily-driver; 27B Q4 is still the LocalRig 24 GB default.
- NVFP4 Spark shoppers. That is another stack; see Spark articles, not this GGUF table.
Methodology
- Fit numbers: Unsloth Gemma 4 hardware table, accessed 2026-09-10. Vendor total-memory bands.
- SKU identity:
google/gemma-4-31B-itHub MCP 2026-09-10 (~31.27B, Apache-2.0, gemma4, image-text-to-text). - Speed: none first-party. Unsloth MTP and GGUF bench notes are vendor, hardware-unspecified here.
- LocalRig first-party: none as of 2026-09-10.
Sources
- Unsloth Gemma 4 local guide — 17–20 GB 4-bit for 31B (accessed 2026-09-10).
- google/gemma-4-31B-it — official card.
- unsloth/gemma-4-31B-it-GGUF.
- Can I run Gemma 4 26B-A4B locally? — MoE sibling.
- Can I run Qwen 3.8 locally? — 24 GB dense default.
- Used RTX 3090 buying guide.
Frequently Asked Questions
Can I run Gemma 4 31B on a used RTX 3090?
Unsloth's 4-bit band is 17–20 GB total memory. A 24 GB 3090 is the consumer card that matches that class at short-to-medium context. LocalRig has no first-party tok/s.
Will a 16 GB card run Gemma 4 31B Q4?
Unsloth's 4-bit floor is 17–20 GB. A 16 GB card is under that band without offload. Prefer 26B-A4B (16–18 GB 4-bit) or a 24 GB card.
Is 31B the same as Gemma 4 26B-A4B?
No. 31B is dense. 26B-A4B is MoE with 4B active. Unsloth says A4B is the speed/quality tradeoff; 31B is the stronger, slower dense SKU.
Does the GGUF include vision?
The official 31B-it card is image-text-to-text. Confirm the specific GGUF/mmproj you download. Do not assume every quant ships a working vision tower.
How fast is Gemma 4 31B on a 3090?
LocalRig has no first-party row. Unsloth's Gemma 4 GGUF benches (their Apr 20, 2026 note) are vendor tables — pin hardware before quoting tok/s. Do not invent a 3090 number.