Can I Run DeepSeek-V4-Pro-0813 Locally? 1.57T Skip/Rent, Not Flash-0731
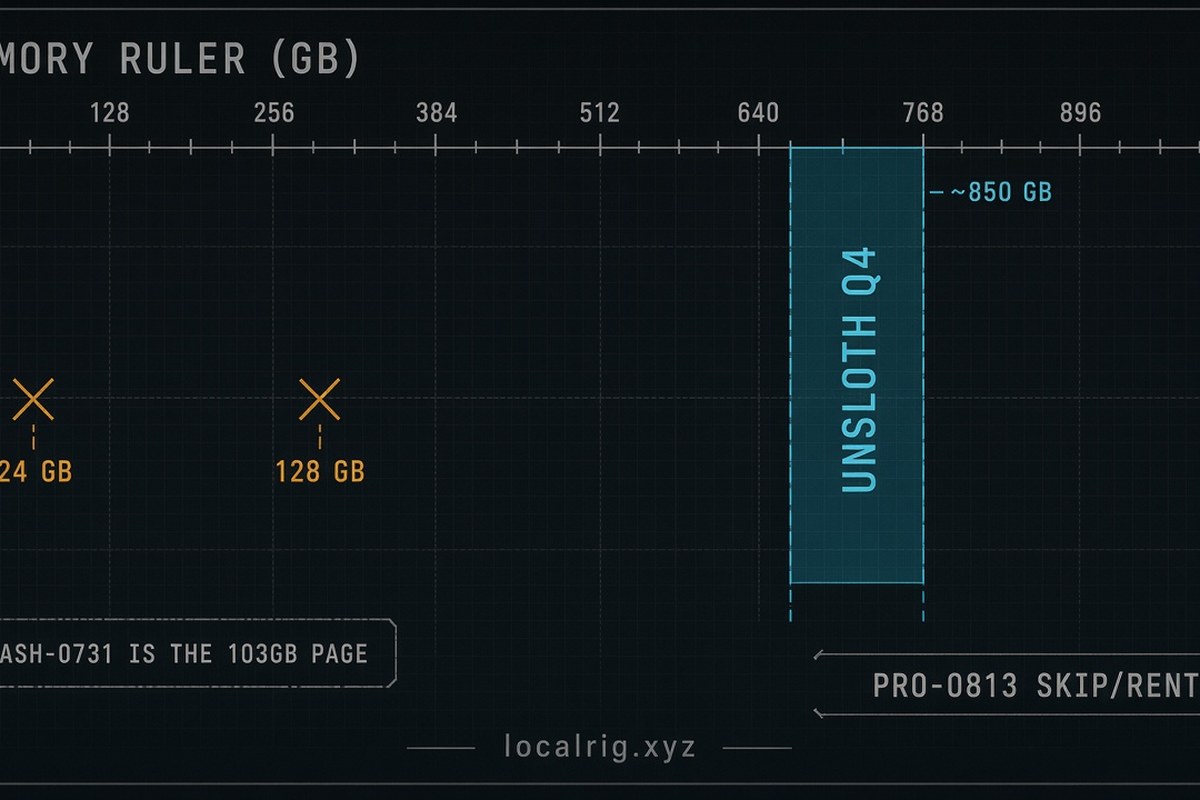
Short answer: DeepSeek-V4-Pro-0813 is deepseek-ai/DeepSeek-V4-Pro-0813. Hub MCP (2026-09-10) lists ~1.65T parameters (1650497.9M). Unsloth GGUF README (same day) 1.57T total / 48B active. Cite both; do not average them. UD-Q4_K_XL is a 20-shard GGUF; community notes of the same Unsloth files put Q4 at 850 GB and Q8 at 873 GB. A used 3090, dual 3090s, and a 128 GB Mac all miss. The 128 GB-class DeepSeek SKU is Flash-0731. Pro is skip or rent. LocalRig has not measured tok/s.
Flash vs Pro vs V4.1-Flash
Three names, two memory planets, plus a new Hub listing. Unsloth’s DeepSeek-V4 guide treats Flash-0731 (284B / 13B active in their copy; ~103 GB 3-bit) and Pro-0813 (1.57T / 48B) as separate GGUF repos. The Pro README repeats: it needs substantially more memory than Flash-0731. DSpark is attached on Pro as on Flash. Vendor quality tables (Terminal Bench 2.1 87.9 on Pro vs 82.7 on Flash) are not a VRAM table and not a reason to download Pro onto a Spark.
DeepSeek-V4.1-Flash on the Hub (updated 2026-09-10) is not this page. No Unsloth Pro math on that SKU.
How large is the Unsloth Q4?
About 850 GB, sharded. Hub ls of unsloth/DeepSeek-V4-Pro-0813-GGUF/UD-Q4_K_XL (2026-09-10) shows 00001-of-00020 through at least 00008-of-00020, with shards ~46 GB after a tiny first file. That is the 850 GB-class download other GGUF repos attribute to Unsloth UD-Q4_K_XL / 873 GB UD-Q8_K_XL. LocalRig is not summing every shard into a fake-precise total; the working statement is Q4 is ~20× ~46 GB, i.e. hundreds of GB, not 103 GB.
A 128 GB unified box is ~15% of that Q4. A 24 GB 3090 is ~3%. This is not “Q4 it until it fits.”
Honest path: rent, or do not buy silicon for Pro
Datacenter multi-GPU or do not purchase a consumer card for this SKU. Official vLLM/SGLang recipes in the DeepSeek-V4 family are GB300-class for Flash; Pro is larger. Try-before-buy: RunPod, Vast.ai, GPUMart, Vultr GPU Cloud for A100/H100/L40S inventory. H100 rental comparison. Rent vs buy.
Browse used RTX 3090 on eBay → only for Qwen 3.8 27B or Flash-0731 if you also have 128 GB — not for Pro.
Check Mac Studio on Amazon → for Flash-0731 3-bit, not for an 850 GB Pro Q4.
Unsloth’s Flash hardware table (92–169 GB depending on quant and DSpark) is the other SKU. Copying Flash 3-bit 103 GB onto Pro is how this site already failed once on the live Flash URL. Pro-0813 GGUF README is explicit: substantially more memory than Flash-0731. Preview Pro vs 0813: 0813 supersedes preview and adds DSpark. Do not download preview weights thinking they are smaller enough for a Spark.
Shard 00001-of-00020 at 5.3 MB is a GGUF header/stub pattern; the following ~46 GB shards are the weights. You need disk for all shards plus a merge or a loader that follows the split. A 2 TB NVMe is a storage constraint before VRAM. Homelab NAS for model storage exists as a cluster article; it does not make Pro fit a 3090.
Vendor quality: Pro Terminal Bench 2.1 87.9 vs Flash 82.7. That gap does not pay for 750 GB of extra weights on a home box. If you want DeepSeek locally on 128 GB, stay on Flash-0731. If you want DeepSeek quality at Pro scale, rent.
Encoding folder / no Jinja on the official card is a runtime footgun, not a memory discount.
qtum and 6block GGUF repos exist for lower-bit Pro quants (IQ1, Q2, Q3). Those are other quantizers. This page’s working Unsloth Q4 is already ~850 GB. A third-party IQ1 that claims 200 GB would need its own cite packet (URL, date, PPL, hardware). llmrun and similar SEO VRAM tables are not Unsloth. Do not mix them into the 850 GB Unsloth Q4 story.
Preview vs 0813: do not keep preview checkpoints to “save disk.” 0813 is the official Pro release with DSpark. Flash-0731 remains the local DeepSeek SKU.
Disk: plan ~1 TB free for Q4 shards plus scratch. That is a NAS/homelab storage article, not a 3090.
Compared with Kimi K3 (594 GB 1-bit) and Kimi K2.6 (350 GB 2-bit), Pro Q4 ~850 GB sits between K3 1-bit and K3 Q4 (1,510 GB). All three are skip/rent. Flash-0731 is the only DeepSeek SKU in this batch that matches 128 GB unified at 3-bit.
DSpark on Pro needs still more memory than dense GGUF, same extra-headroom story as Flash. Do not enable DSpark to “make it fit.” It makes the bill larger.
MIT license on Pro matches Flash. License is not VRAM. arXiv 2606.19348 is the V4 report for the family.
If a host lists “DeepSeek V4” without 0731 vs 0813, ask which GGUF repo. Flash 103 GB vs Pro 850 GB is the whole decision.
Hub vs Unsloth total-parameter copy (1.65T vs 1.57T) is the same class of disagreement as Flash-0731 (~304B Hub overview vs Unsloth 284B). The buy constraint is the GGUF, not which lab’s headline trillion you prefer. 1.57T and 1.65T both imply an 800 GB+ Q4, not a 103 GB 3-bit.
What to run instead
24 GB: Qwen 3.8 27B Q4, GLM-4.7-Flash, or gpt-oss-20b on 16 GB. Those are the LocalRig 24 GB-class SKUs in this batch. Pro is not a “Q2 it until it fits” guest on a 3090.
128 GB unified (Mac / Spark): Flash-0731 at Unsloth 3-bit ~103 GB, or GLM-5.3-Flash 3-bit. Still not Pro. A Spark cube is 128 GB unified, not 850 GB.
Rent: size the node to the GGUF plus KV, not to “DeepSeek” as a brand. Multi-GPU H100/B200 inventory is the honest try path. Affiliate lanes: RunPod, Vast.ai, GPUMart, Vultr GPU Cloud. Vultr is datacenter A100/H100/L40S, never a consumer 4090 for this SKU. Break-even vs buying an 850 GB box: rent vs buy GPU.
Official Hub inference providers on the Pro card are API paths. They do not shrink the GGUF. If the goal is “use Pro quality,” API or a sized rental is the honest product. If the goal is “own the weights on a used 3090,” the SKU is wrong.
Who this is NOT for
- Flash-0731 shoppers who landed on Pro. 103 GB vs ~850 GB.
- 24 GB and 128 GB buyers. Wrong SKU.
- Anyone treating vendor Terminal Bench scores as a hardware requirement.
- Readers who need LocalRig tok/s on Pro. None. Flash B200 DSpark numbers stay on the Flash page.
- V4.1-Flash curiosity. Different Hub repo; no Pro math.
Methodology
- SKU identity: Hub MCP 2026-09-10
deepseek-ai/DeepSeek-V4-Pro-0813~1.65T; Unsloth Pro GGUF README 1.57T / 48B active, DSpark. Both cited; not averaged. - Fit numbers: Hub ls of UD-Q4_K_XL shards (~20 × ~46 GB) plus community restatement of Unsloth 850 / 873 GB. Not a LocalRig byte-sum.
- Speed: none first-party.
- LocalRig first-party: none as of 2026-09-10.
Sources
- deepseek-ai/DeepSeek-V4-Pro-0813 — Hub MCP 2026-09-10, ~1.65T.
- unsloth/DeepSeek-V4-Pro-0813-GGUF (Hub MCP 2026-09-10).
- Unsloth DeepSeek-V4 local guide.
- Can I run DeepSeek-V4-Flash-0731 locally?.
- Can I run Qwen 3.8 locally?.
- H100 rental price comparison.
Frequently Asked Questions
Can I run DeepSeek V4 Pro on a 3090 or 128 GB Mac?
No. Unsloth documents 1.57T / 48B active. UD-Q4_K_XL is a ~20-shard GGUF around 850 GB. Flash-0731 is the 128 GB-class SKU. Pro is skip/rent.
Is Pro the same as Flash-0731?
No. Flash-0731 is Unsloth's ~103 GB 3-bit path. Pro-0813 is the 1.57T flagship. Mixing names is how a Spark shopper downloads an 850 GB file.
Is V4.1-Flash this model?
No. deepseek-ai/DeepSeek-V4.1-Flash appeared as a Hub listing on 2026-09-10. This page is Pro-0813 only.
How fast is Pro locally?
LocalRig has no first-party row. Do not transplant Flash B200 DSpark 120 tok/s onto Pro.
What should I run instead on 24 GB?
Qwen 3.8 27B Q4, or Flash-0731 only if you have 128 GB unified.