Can I Run DeepSeek-V4-Flash-0731 Locally? 284B MoE, Not a 14B Card
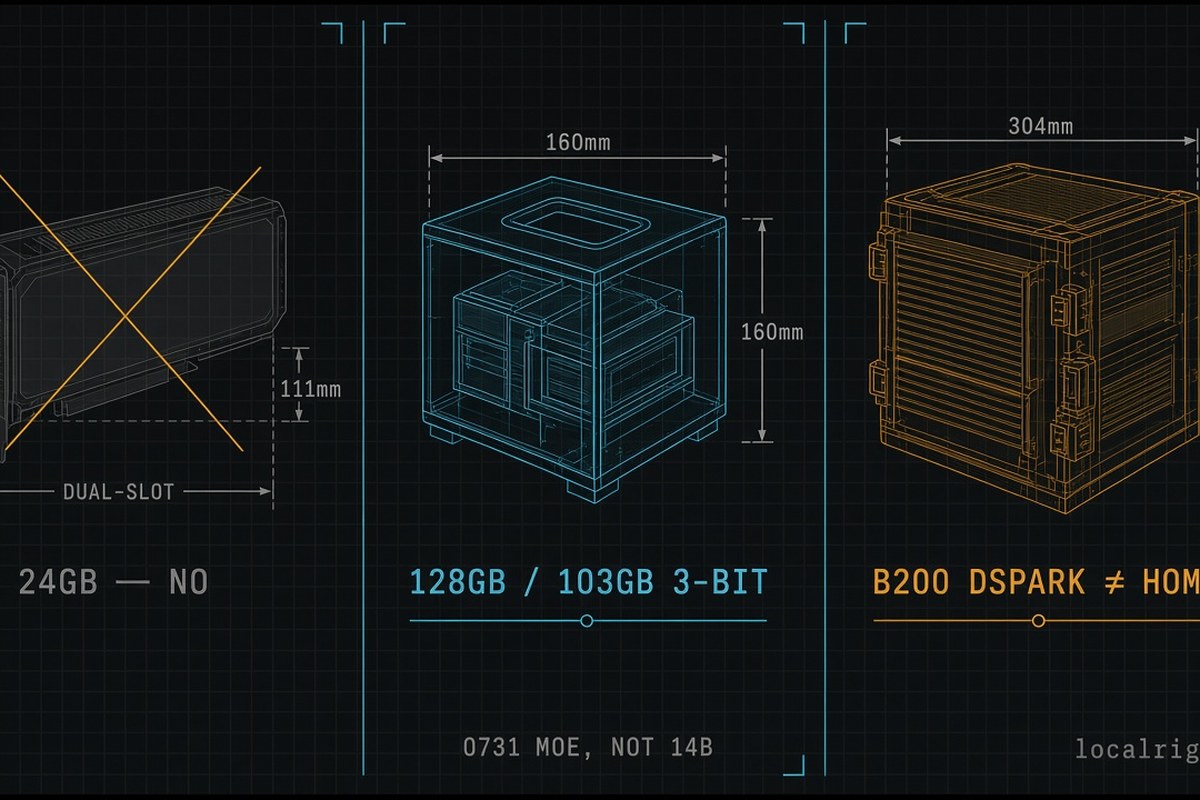
Short answer: DeepSeek-V4-Flash-0731 is not a 14B local-coding toy. Unsloth documents 284B total / 13B active with a 1M context window. The GGUF they recommend for 128 GB machines is UD-IQ3_XXS (~103 GB) with ~110 GB of total memory. A used RTX 3090 or 4090 cannot load the weights. The honest local paths are a 128 GB Mac / DGX Spark at 3-bit, a large RAM box with offload, or a multi-GPU rental. LocalRig has not measured tok/s on this SKU.
This page replaces the earlier 7–8 GB Q4 table that lived on this URL. That math described a different (nonexistent-here) 14B dense model. If you bought a 12 GB card because of the old copy, the buy was for Qwen 3.8 27B Q4, not this MoE.
Is this the same model as DeepSeek-V4-Pro or V4.1-Flash?
No. Unsloth’s DeepSeek-V4 guide covers Flash-0731 and Pro-0813 as separate SKUs. Flash is the smaller MoE (284B / 13B active in their copy). Pro is 1.6T / 49B active. Mixing those names is how a 24 GB shopper ends up staring at a 100 GB file.
Hugging Face Hub (accessed 2026-09-10) lists deepseek-ai/DeepSeek-V4-Flash-0731 at ~304.2B parameters, MIT license, architecture deepseek_v4, updated 1 Aug 2026, ~5.8M downloads. Unsloth’s prose says 284B. LocalRig is not picking a “true” count. Use the file size on the GGUF you actually download.
A later Hub repo, deepseek-ai/DeepSeek-V4.1-Flash, showed an update timestamp of 2026-09-10. That is a different listing. This page does not size V4.1. No Unsloth memory table for V4.1 is cited here.
The official 0731 card states it supersedes the Flash preview, ships with a DSpark speculative-decoding module (same structure as DeepSeek-V4-Flash-DSpark), and reports vendor scores such as Terminal Bench 2.1 82.7. Those scores are DeepSeek’s evaluation protocol (max reasoning, temperature 1.0, top_p 0.95 for agentic tasks). They are not a VRAM table and not a LocalRig ranking against Kimi K2.6.
How much memory does DeepSeek-V4-Flash-0731 need?
About 103 GB at Unsloth’s 3-bit recommendation, ~162 GB for their lossless Q8, with DSpark adding ~10 GB. Copied from Unsloth (accessed 2026-09-10). Units are total memory: RAM + VRAM, or unified memory. File size does not include KV cache.
| Format | 1-bit | 2-bit | 3-bit | 4-bit (near lossless) | Q8_K_XL (lossless) |
|---|---|---|---|---|---|
| Standard | 92 GB | 102 GB | 110–135 GB | 162 GB | 169 GB |
| DSpark | 102 GB | 112 GB | 120–145 GB | 172 GB | 179 GB |
Unsloth’s recommended download for “fits a 128 GB RAM device” is UD-IQ3_XXS (103 GB); they tell you to have at least 110 GB. UD-Q8_K_XL is 162 GB on disk and they want ≥169 GB. UD-Q4_K_XL sits next to Q8 in size because routed experts stay native MXFP4 (96% of the model) and only the remaining tensors are downcast — so “Q4” here is not a 24 GB card trick.
Context on the vendor card is 1,048,576 tokens. Think Max wants at least 384K output budget in DeepSeek’s own notes. A machine that “just fits” 3-bit at a short window will not also hold a filled 1M KV cache. LocalRig has no first-party KV measurement for this architecture. Use the VRAM calculator only as a generic overlay, then treat the Unsloth bands as the working floor.
Can a 24 GB card run DeepSeek-V4-Flash-0731?
No. A 24 GB RTX 3090 or 4090 is about one-quarter of Unsloth’s 3-bit file. Two used 3090s give 48 GB of device memory, which is still under 1-bit (92 GB) and far under 3-bit. This is not a “Q4 it until it fits” problem. The 3-bit file is already ~103 GB.
If your silicon is a single 24 GB card, the current dense daily driver on LocalRig is Qwen 3.8 27B Q4, including the used 3090 4k–32k cell. A used 3090 is still a valid buy for 27B. It is not a DeepSeek-0731 buy.
Browse used RTX 3090 24GB on eBay → only if you are shopping 27B-class models. Do not buy a 3090 expecting 0731 to load.
What local machines actually fit Unsloth’s table?
128 GB unified (Mac Studio / DGX Spark) at 3-bit, or more RAM/VRAM than the file. Unsloth’s own tutorial uses UD-IQ3_XXS because it is the quant they say fits a 128 GB device. DSpark is “automatically enabled” in Unsloth Desktop and needs the extra ~10 GB; a 128 GB box running DSpark is tighter than the same box without the draft model.
LocalRig has no Mac Metal tok/s and no Spark tok/s for 0731. Unsloth’s speed cite for DSpark is ~120 tok/s vs ~60 tok/s baseline on a B200. Community-cited, B200-only. Do not paste that onto a Spark cube.
Official vLLM on the 0731 card is a 4×GB300 node example with --speculative-config '{"method":"dspark",...}'. That is datacenter serving, not a consumer 4090 recipe. SGLang’s cookbook likewise names GB300-class hardware. If you want to try that stack before buying a 128 GB box, rent inventory — do not assume one 80 GB H100 holds 103 GB of weights plus KV.
Check Mac Studio 128GB on Amazon →
DGX Spark vs dual RTX 3090 is the 128 GB vs 48 GB split — dual 3090 still loses the DeepSeek-0731 fit. For a try-before-buy on large GPUs: RunPod, Vast.ai, GPUMart GPU hosting. Datacenter A100/H100/L40S catalog (not a 4090): Vultr GPU Cloud.
llama.cpp vs vLLM vs Ollama — what is actually documented?
llama.cpp GGUF (Unsloth) is the documented home path. Official vLLM/SGLang are multi-GPU datacenter recipes. Ollama filled-context tok/s for 0731 is a shortfall.
Unsloth’s llama.cpp path: latest llama.cpp, -hf unsloth/DeepSeek-V4-Flash-0731-GGUF:UD-IQ3_S (their snippet) or a manual split GGUF, temperature = 1.0, top_p = 1.0 (or 0.95 for agentic 0731). DSpark in llama.cpp: download the draft GGUF, --spec-type draft-dspark, --spec-draft-n-max 3, extra ~10 GB. They point at llama.cpp PR 25784 for DSpark.
Official card: no Jinja chat template in-repo; use the encoding folder. Reasoning effort: low / high / max. High/max: they want max output length 384K.
Ollama: LocalRig has no named library tag + tok/s packet for 0731 on a 128 GB box as of 2026-09-10. If you only have an Ollama one-liner from a blog with no hardware, that is not a cell.
Related runtime overview: Ollama vs llama.cpp vs vLLM.
Who this is NOT for
- Anyone who still thinks this URL is a 14B / 7 GB Q4 guide. That copy was wrong. The live SKU is 0731 at ~103 GB 3-bit.
- Buyers with a 12–24 GB Ampere or Ada card. Wrong SKU. Use Qwen 3.8 27B.
- People collapsing Flash-0731 into V4-Pro or into Hub’s V4.1-Flash listing. Different files, different memory class.
- Anyone treating Unsloth’s B200 DSpark 120 tok/s as a Spark or Mac number. Different hardware. Shortfall stays visible.
- Shoppers who need LocalRig first-party tok/s before they will believe the file size. There is no
engine.dbrow. The file size is still ~103 GB.
Methodology
- Fit numbers: Unsloth hardware table and GGUF sizes, accessed 2026-09-10 from https://unsloth.ai/docs/models/deepseek-v4 and
unsloth/DeepSeek-V4-Flash-0731-GGUF. Vendor estimates, not LocalRig measurements. - SKU identity: Official card
deepseek-ai/DeepSeek-V4-Flash-0731via Hugging Face Hub MCP (2026-09-10): ~304.2B listed parameters, MIT, DSpark notes, vLLM 4×GB300 example. Unsloth copy: 284B / 13B active. Discrepancy left visible. - Speed numbers: Unsloth DSpark ~120 tok/s vs 60 tok/s on B200. Not transferable to 3090 / Spark / Mac.
- LocalRig first-party: none for DeepSeek-V4-Flash-0731 as of 2026-09-10.
Sources
- Unsloth DeepSeek-V4 local guide — 284B/13B, 103 GB 3-bit, 110 GB floor, DSpark +10 GB, B200 120 vs 60 tok/s, sampling (accessed 2026-09-10).
- unsloth/DeepSeek-V4-Flash-0731-GGUF — GGUF + DSpark draft files.
- deepseek-ai/DeepSeek-V4-Flash-0731 — official card, DSpark, vLLM/SGLang, encoding folder (Hub MCP 2026-09-10).
- Can I run Qwen 3.8 locally? — 24 GB dense path.
- Can I run Kimi K2.6 locally? — 1T skip/rent, not a 14B peer.
- DGX Spark vs 2× RTX 3090 — 128 GB unified vs 48 GB split.
- Rent vs buy a GPU — when rental beats a 128 GB purchase.
Frequently Asked Questions
Can I run DeepSeek V4 Flash on a used RTX 3090 or 4090?
No. Unsloth's 3-bit band is about 103 GB of weights plus headroom. A 24 GB card cannot hold the file. Two 3090s (48 GB) still miss the floor. This is a 128 GB-class machine or a multi-GPU rental.
Is DeepSeek-V4-Flash a 14B model?
No. That figure was a LocalRig error on this URL. The 0731 card is DeepSeek-V4-Flash with Unsloth documenting 284B total and 13B active. Hugging Face Hub lists ~304B parameters on the same repo. Neither number is 14B.
Will a 128 GB Mac Studio or DGX Spark run it?
Unsloth's recommended UD-IQ3_XXS is a 103 GB file and they want at least 110 GB of RAM/VRAM or unified memory. A 128 GB Mac or Spark is the local class they describe for 3-bit. DSpark speculative decoding needs about 10 GB more. LocalRig has no first-party tok/s on either machine.
Is DeepSeek-V4-Flash-0731 the same as V4-Pro or V4.1-Flash?
No. V4-Pro is the 1.6T / 49B-active flagship. V4.1-Flash appeared as a separate Hub listing on 2026-09-10. This page is only 0731.
How fast is it locally?
LocalRig has no first-party row. Unsloth cites DSpark reaching about 120 tok/s versus 60 tok/s baseline on a B200. That is a B200, not a Spark, not a Mac, not a 3090. Do not transplant it.