Can I Run Kimi K3 Locally? 2.8T / 594 GB 1-bit, Not K2.6
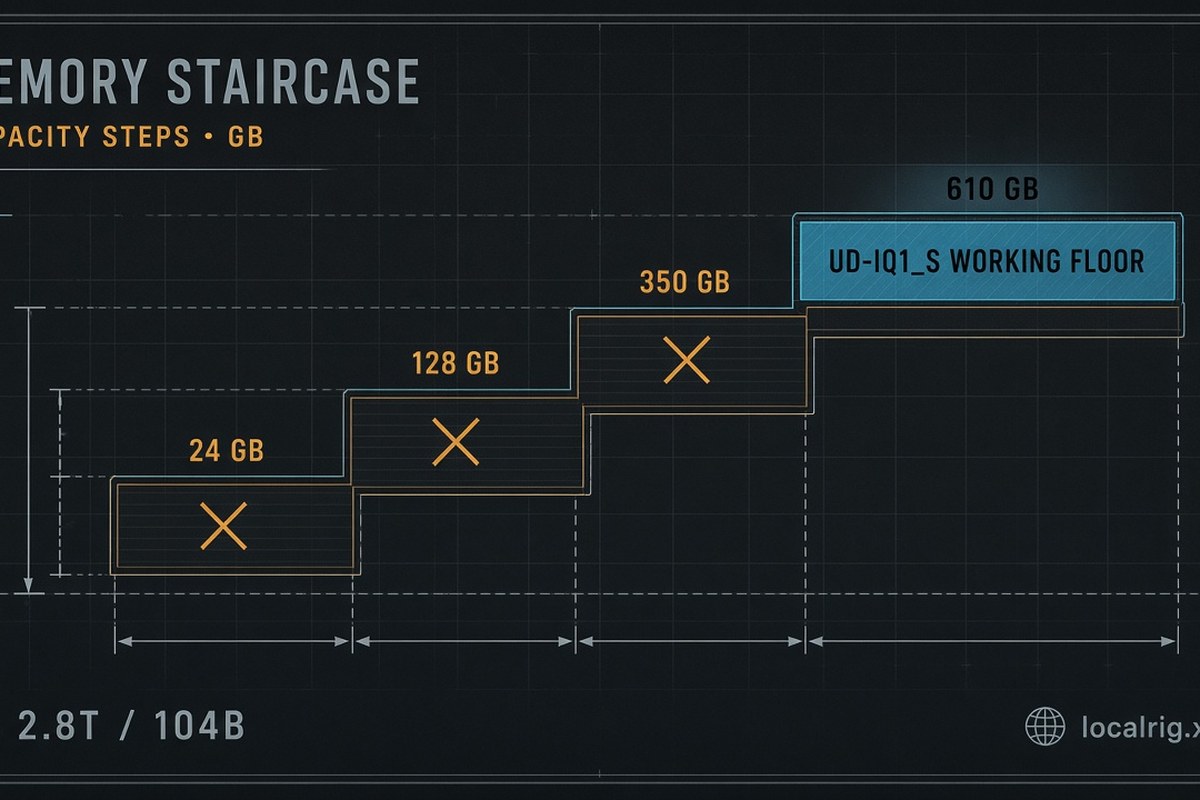
Short answer: Kimi K3 is moonshotai/Kimi-K3: 2.8T total / 104B active, native vision, 1M context, MXFP4 MoE. Unsloth UD-IQ1_S is 594 GB and they want ~610 GB total memory. Hub lists ~2.78T parameters (2026-09-10). A used 3090, a 128 GB Mac, and even K2.6’s 350 GB class all miss. Skip or rent. LocalRig has not measured tok/s.
K3 is not K2.6 with a paint job
About 2.8× the total parameters, and Unsloth’s 1-bit file is already larger than K2.6’s 2-bit. Hub: architecture kimi_k3, ~4.2M downloads, 11.3k likes. Unsloth: full precision 1.56 TB disk; Dynamic 1-bit 594 GB (62% smaller in their copy); Dynamic 2-bit 861.3 GB. Lossless Q8 follows MXFP4 experts + BF16 rest.
Unsloth hardware table (accessed 2026-09-10), total memory:
| Dynamic 1-bit S | Dynamic 1-bit M | Dynamic 2-bit XXS | Dynamic 2-bit XL | Q8 (lossless) |
|---|---|---|---|---|
| 610 GB | 665 GB | 726 GB | 880 GB | 1.6 TB |
Quant table on the same page: UD-IQ1_S 594.0 GB, UD-IQ1_M 648.9 GB, UD-IQ2_XXS 711.1 GB, UD-Q2_K_XL 861.3 GB, UD-Q4_K_XL 1,510 GB, UD-Q8_K_XL 1,560 GB.
The sentence about a Mac Studio connected to a 128 GB RAM device is not “K3 fits 128 GB unified.” 594 GB does not fit 128 GB. Read it as extra host RAM, or ignore it as marketing-adjacent. LocalRig treats 610 GB as the 1-bit working floor.
24 GB / 128 GB / 350 GB — all skip
3090 ≈ 4% of 1-bit. 128 GB ≈ 21%. K2.6’s 350 GB 2-bit ≈ 57% of K3 1-bit. You cannot “almost” fit this. Offload to disk is Unsloth’s “it still works, much slower” path — not a LocalRig daily-driver cell.
Browse used RTX 3090 on eBay → for 27B.
Mac Studio on Amazon → for Flash-0731 or GLM-5.3-Flash 3-bit, not K3.
Rent: RunPod, Vast.ai, GPUMart, Vultr GPU Cloud. Unsloth speed cite: ~20 tok/s generation on B200s if it fits, >120 tok/s throughput. Community-cited, B200-only.
Runtime shortfalls
llama.cpp via Unsloth’s fork (vision PR), not a random llama.cpp tag. They document unslothai/llama.cpp checkout kimi-k3-fullsize-vision, mmproj-BF16, UD-IQ1_S. Sampling: temperature 1.0, top_p 0.95 (agentic top_p 1.0). Context up to 1,048,576. Thinking-only. LocalRig will not paste their Unsloth Studio URL that includes loopback addresses.
Ollama: no packet. Do not invent one.
Related: K2.6, K2.7-Code, DeepSeek-V4-Pro.
Unsloth’s warning about other community 1-bit GGUFs (example IQ1_M at 618.9 GB with PPL 54 vs their 594 GB at 2.58) is a quant quality story, not a reason to buy a 3090. Even the “good” 1-bit is 594 GB. DGX Station is the class they name; a used 3090 is not a Station.
Preserve-thinking always on means KV grows with traces you cannot delete. Combined with 1M max context, this is the opposite of a small-card SKU. llama.cpp n_tokens * 160 budget note on their fork is a runtime footgun for operators who already have 610 GB — still irrelevant to 24 GB.
Do not cite Hub likes (11k) as a local-runnability signal. Can I run MiniMax M3 locally? is another 100 GB+ multimodal MoE; K3 is an order of magnitude above that 1-bit floor.
Unsloth is “still investigating if we can push it under 512GiB (dynamic 1-bit is 553.2 GiB)” — even that research floor is four Spark cubes, not one. Do not wait for a 24 GB quant. It will not arrive as a 3090 file.
B200 ~20 tok/s generate / >120 tok/s throughput is the only speed sentence on their page. DGX Station is named. A Mac Studio plus a second 128 GB box is still not 610 GB unless you actually attach that RAM. Read the bill of materials, not the adjective “Mac.”
K3 vs DeepSeek Pro: both are skip/rent. K3 1-bit 594 GB vs Pro Unsloth Q4 ~850 GB. Neither is Flash-0731. If the question is “largest open Moonshot on a home box,” the answer is still none of K2.6 / K2.7 / K3 on 24 GB.
Thinking effort low/high/max changes decode time on a machine that fits. It does not create a 128 GB fit.
Unsloth llama.cpp fork for vision is a build pin. Stock llama.cpp tags may fail. That is an operator cost on a 610 GB box, not a 3090 issue.
NAS for AI model storage if you actually pull 594 GB. Storage is the easy part. Memory is not.
Hub MCP (2026-09-10): moonshotai/Kimi-K3 ~2.78T (2779931.8M), architecture kimi_k3, ~4.2M downloads, ~11.3k likes. Unsloth copy is 2.8T / 104B active. Cite both. Downloads are not a 128 GB fit.
What to run instead
24 GB: Qwen 3.8 27B remains the LocalRig dense daily driver. K3 will not become a 3090 file.
128 GB: DeepSeek-V4-Flash-0731 (~103 GB 3-bit) or GLM-5.3-Flash 3-bit. K3 1-bit at 594 GB is still about 4.6× that class. Unsloth’s “Mac Studio connected to a 128 GB RAM device” line is extra host RAM, not a Studio-only fit.
K2.6 / K2.7-Code class (350–595 GB): those SKUs are still smaller than K3. If you already bought that box for K2.6, K3 1-bit at ~610 GB working memory is a step up, not a free upgrade. Q4 at 1,510 GB is another planet again.
Rent: B200-class or DGX Station-class inventory if you need the vendor thinking model. Unsloth’s only speed sentence is ~20 tok/s generate on B200s if it fits, >120 tok/s throughput. Community-cited, B200-only. Lanes: RunPod, Vast.ai, GPUMart, Vultr GPU Cloud.
Do not wait for a 24 GB K3 quant. Unsloth’s research floor under 512 GiB is still four Spark cubes, not one 3090.
Who this is NOT for
- K2.6 / K2.7-Code shoppers who wanted 350–595 GB, not 594 GB 1-bit on a 2.8T model. K3 is larger.
- 128 GB Mac / Spark buyers. Wrong class.
- People quoting Unsloth B200 20 tok/s as a Mac number.
- Anyone who needs Instant/non-thinking. Unsloth: not supported.
- 24 GB shoppers. Qwen 3.8 27B.
Methodology
- Fit numbers: Unsloth Kimi K3 guide, 2026-09-10 (594 GB UD-IQ1_S, 610 GB working rule, 1,510 GB Q4).
- SKU identity: Hub MCP ~2.78T; Unsloth 2.8T / 104B active, 1M context.
- Speed: Unsloth ~20 tok/s gen on B200 if it fits. Not transplanted.
- LocalRig first-party: none as of 2026-09-10.
Sources
Frequently Asked Questions
Can a 128 GB Mac Studio run Kimi K3?
No. Unsloth's smallest practical 1-bit GGUF is 594 GB on disk and they want ~610 GB RAM/VRAM. 128 GB is about one-fifth of that. Their 'Mac Studio connected to a 128GB RAM device' line is extra RAM, not a 128 GB-only fit.
Is K3 the same as K2.6?
No. K2.6 is 1T / 32B, Unsloth 2-bit ~350 GB. K3 is 2.8T / 104B, Unsloth 1-bit 594 GB. Different skip class.
Will Q4 make it fit a Spark?
Unsloth UD-Q4_K_XL is 1,510 GB in their quant table. Q8 lossless is 1,560 GB. Higher precision is worse for a 128 GB box, not better.
How fast is K3 locally?
Unsloth says if it fits, ~20 tok/s generation on B200s and >120 tok/s throughput. B200 only. Not a 3090, Spark, or Mac number.
Instant / non-thinking mode?
Unsloth: K3 is thinking-only; instant mode is not supported. reasoning_effort low / high / max.